<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://www.dewanahmed.com/feed.xml" rel="self" type="application/atom+xml" /><link href="https://www.dewanahmed.com/" rel="alternate" type="text/html" /><updated>2026-08-11T14:20:48-03:00</updated><id>https://www.dewanahmed.com/feed.xml</id><title type="html">Dewan’s Blog</title><subtitle>Read about app/data infrastructure, developer advocacy, and my thoughts around a career in tech.</subtitle><author><name>Dewan Ahmed</name></author><entry><title type="html">The Third Reset: Becoming a Developer Advocate in the AI Era</title><link href="https://www.dewanahmed.com/devrel-ai-era/" rel="alternate" type="text/html" title="The Third Reset: Becoming a Developer Advocate in the AI Era" /><published>2026-08-11T01:00:00-03:00</published><updated>2026-08-11T01:00:00-03:00</updated><id>https://www.dewanahmed.com/devrel-ai-era</id><content type="html" xml:base="https://www.dewanahmed.com/devrel-ai-era/"><![CDATA[<p>Someone asked me recently what advice I’d give to a person trying to break into DevRel in the AI era. I gave an answer around “something something AI”. But then it bothered me -.- so this blog is me answering that question, again.</p>

<p>In reality, the AI era is not a new job. It’s the third reset of the same job, and it only looks unprecedented if you weren’t paying attention during the first two.</p>

<p>Ask five experienced developer advocates what to focus on and you’ll get seven different answers, all correct. Learn AI. Learn AI. Learn AI. Learn video. Learn marketing and events, because that’s what the postings actually ask for. Learn agentic development. Learn how to size up an organization so you don’t become the first DevRel hire at a ten person company that has no idea what it just bought. That’s seven answers from five people, and three of them are the same answer said louder. Nobody on that list is wrong. Now try building a twelve month plan out of it :)</p>

<p>I started my big tech career at IBM in 2014, spent 2020 to 2022 at Red Hat, and have been at startup unicorns since. I’ve also been organizing conferences and meetups for the last decade or so, which means twice a year I read a stack of CFP submissions and watch the industry’s obsessions turn over in real time, usually about nine months before they show up in job descriptions. From that seat, the pattern is hard to miss.</p>

<p>I want to explore five things in this blog:</p>

<ol>
  <li>The three eras of developer advocacy, what changed at each reset, and what has never changed at all.</li>
  <li>How the demos we build changed, including the sharp break of the last three years.</li>
  <li>How DevRel measurement shifted across the eras, and why the AI era quietly broke the metrics most teams still report.</li>
  <li>The uncomfortable truth: you are not hired for what you value. You are hired to remove a cost.</li>
  <li>How to tell whether the job you’re being offered is one where the work is even possible.</li>
</ol>

<h2 id="three-eras-three-complete-resets">Three eras, three complete resets</h2>

<h3 id="era-1-before-the-cluster">Era 1: Before the cluster</h3>

<p>Roughly 2008 to 2014. The title was usually “developer evangelist,” and the product surface you advocated for was small enough to hold in your head: a REST API, an SDK in four languages, a quickstart, and a set of docs.</p>

<p>The distribution channel was <strong>people in rooms</strong>. Conference stages, user groups, hackathons, a book, a blog on your own domain, a mailing list. Companies like Twilio, SendGrid, EngineYard, and New Relic took the model mainstream by putting engineers, not marketers, on stage in front of other engineers.</p>

<p>When I joined IBM in 2014, the hardest part of the job was explaining that the job existed. “What do you do at IBM?” never ended in one sentence. I eventually got so tired of the explanation that I <a href="https://medium.com/@dewanahmed/what-i-do-as-a-developer-advocate-at-ibm-da2252179f6">wrote a blog post</a> I could just send people. Some of my colleagues then were engineers who had spent twenty years shipping software and chose advocacy over management or a principal engineer track. A few of them retired out of the role. That was the profile: <a href="https://www.dewanahmed.com/why-paying-devrel/#developer-advocacy---not-an-entry-level-role">not an entry level job</a>, and nobody pretended otherwise.</p>

<p>Credibility was earned in production and spent on stage. The unit of work was <strong>the talk</strong>.</p>

<h3 id="era-2-the-microservices-kubernetes-and-api-era">Era 2: The microservices, Kubernetes, and API era</h3>

<p>Docker landed in 2013. Kubernetes in 2014. The CNCF in 2015. Within about three years, the surface area a developer advocate had to cover went from an SDK and an API to YAML, Helm charts, operators, CRDs, service meshes, observability stacks, CI pipelines, and Terraform.</p>

<p>Two things changed at once, and they’re worth separating.</p>

<p>The technical bar moved sideways, not up. Writing good application code stopped being sufficient. You had to run a distributed system, explain why it fell over, and reason about failure across a network boundary. Some developer advocates looked at Kubernetes in 2016, decided it was accidental complexity dressed up as progress, and sat that cycle out. That was a defensible engineering opinion. It was a bad advocacy decision, and the two are not the same thing. An engineer can stay valuable maintaining an unfashionable system. An advocate for an unfashionable system has no audience.</p>

<p>Sit with that, because it’s the pattern that governs everything else in this post. <strong>The market’s demand did not need to be architecturally justified in order to be real.</strong></p>

<p>My own version of that lesson came at the transition. I came up as a backend Java developer. Around 2016 I had to decide whether the container thing was a serious shift or a fashion, and I chose to treat it as serious mostly because the CFP submissions I was reading as an organizer had gone from ten percent container talks to sixty percent in about two years. I didn’t reach that by evaluating the architecture. I reached it by counting talk submissions, which turned out to be the better instrument.</p>

<p>By the time I got to Red Hat in 2020, the reset was complete and the demo had become an environment rather than a snippet. It was also the pandemic, so every event I organized or spoke at moved to a webcam, which stripped out the hallway track and left only the artifact. That accelerated something already underway.</p>

<p><strong>The distribution channel had moved to search and GitHub.</strong> The talk stopped being the unit of work. The unit became the artifact that outlived you: the tutorial that ranked on page one, the reference architecture repo people forked, the docs page that surfaced when someone pasted an error message into Google. A conference talk was a spike. A tutorial was an annuity.</p>

<p>The unit of work was <strong>the artifact</strong>.</p>

<h3 id="era-3-the-ai-era">Era 3: The AI era</h3>

<p>Now look at what’s actually happening, and look past the word “AI,” which is so overloaded it carries almost no information.</p>

<p><strong>The product surface changed again.</strong> It’s a model, a set of tools, an MCP server, a retrieval layer, an eval suite, a context budget, and a bill that scales with tokens instead of nodes. If you advocate for a developer product today, a growing fraction of your product’s usage is driven by an agent that a human is loosely supervising.</p>

<p><strong>The distribution channel changed again, and this is the part most people are underweighting.</strong> In Era 1 you reached a human in a room. In Era 2 you reached a human through a search engine. In Era 3, a large share of your content is read by a model before a human sees it, and frequently instead of. RTFM is being replaced by the AI reading the manual on the developer’s behalf. Your developer portal’s job is no longer only to be readable. It has to be <strong>retrievable and unambiguous</strong> to something that will never scroll.</p>

<p>I wrote about <a href="https://www.dewanahmed.com/llms-txt/">llms.txt</a> a while back and the reaction was mostly polite curiosity. It isn’t curious anymore. If an agent cannot get from zero to a working integration with your product without a human intervening, you have a developer experience problem that no amount of conference presence will fix.</p>

<p>There’s a second order effect that I think is the real story of this era. <strong>The cost of producing a competent-looking artifact has fallen to nearly zero.</strong> A tutorial, a demo app, a blog post, a sample repo, all of it can be generated in an afternoon by someone who understands none of it.</p>

<p>That breaks the Era 2 economy completely. For fifteen years the artifact was evidence. It was expensive to produce, so producing one proved something about you. Publishing a lot used to mean you had worked hard, and working hard used to mean you knew something. Both of those chains snapped.</p>

<p>When artifacts stop working as evidence, the market re-prices two things: <strong>judgment</strong> and <strong>verifiable outcomes</strong>. Knowing what to build, knowing when the agent is confidently wrong, knowing the exact moment to take manual control back. Typing was never the hard part of this job. It was just the last reliable proxy we had for someone who could do the rest, and it stopped working.</p>

<p>The unit of work is <strong>the judgment call</strong>.</p>

<h2 id="the-demo-tells-the-whole-story">The demo tells the whole story</h2>

<p>If you want a single artifact that tracks all three eras, watch what happened to the demo.</p>

<p><strong>Era 1: the demo was proof the API worked.</strong> A laptop, a terminal, a browser, five minutes of live coding that ended with a text message arriving on a phone in front of 300 people. Small, deterministic, genuinely persuasive because the audience saw the whole thing. Shelf life of two or three years. You could give it at eight conferences and only bump the SDK version.</p>

<p><strong>Era 2: the demo became an environment.</strong> You weren’t showing an API call, you were showing a system. A polyglot microservices app, a GitOps pipeline, a cluster that had to exist before the talk started. A week to build, half a day to reset. Half the room had seen a variation already, because the whole ecosystem was demoing against the same reference apps. The demo stopped proving your product worked and started proving your product fit into a stack. Shelf life of about a year, because a minor version bump could break it on stage. I have watched a demo die at a meetup because of a Helm chart change that shipped that morning, and the recovery mattered more to that room than the demo would have.</p>

<p><strong>Era 3, specifically the last three years, is where it gets interesting.</strong> The trajectory ran chatbot, then RAG pipeline, then agent, then multi-agent, roughly one per year. But the version number isn’t the point. Three deeper things changed:</p>

<p><strong>The demo stopped being scarce, so it stopped being persuasive.</strong> When the audience knows anyone can generate a polished demo app in an hour, watching one generated live impresses nobody. The demo lost its function as proof of competence. That’s a genuine loss and our field has not adjusted to it. Plenty of teams are still shipping Era 2 style demos and wondering why engagement is flat.</p>

<p><strong>Demos became non-deterministic.</strong> You can no longer guarantee the same output twice. Anyone who has run a live agent demo knows the specific dread of watching the model take a path you never saw in forty rehearsals. The honest responses are to pin versions and seeds, to pre-record and narrate over it, or to lean into the non-determinism deliberately and make the recovery the point.</p>

<p><strong>Shelf life collapsed to weeks.</strong> A demo built against a model release from six months ago is often just wrong, not merely dated. The cost structure inverted: cheap to produce, expensive to maintain. Most teams have not updated their budgets for that.</p>

<p>So what actually persuades a technical audience now? Three things, in my experience:</p>

<ul>
  <li><strong>The demo that fails on purpose.</strong> Show the agent getting it wrong, show how you caught it, show the guardrail. Everyone in the room has been burned by something that didn’t survive contact with real data. Showing the failure mode buys more credibility than a clean run ever will.</li>
  <li><strong>The eval, not the output.</strong> A passing eval suite is the new working demo. It survives a version bump, and it’s the artifact a skeptical staff engineer actually respects.</li>
  <li><strong>The demo an agent can run without you.</strong> If someone points their own agent at your repo and reaches the same result unattended, you’ve proven something about your product’s agent experience that no stage performance can.</li>
</ul>

<h2 id="what-we-measured-and-what-quietly-broke">What we measured, and what quietly broke</h2>

<p>Metrics moved in lockstep with distribution, and the AI era broke a set of proxies most teams are still reporting.</p>

<p><strong>Era 1 measured presence.</strong> Attendance, booth conversations, t-shirts, tweets, a warm feeling in the exec team. Nobody had solved attribution because nobody was seriously asking.</p>

<p><strong>Era 2 measured traffic and community.</strong> Docs pageviews, search rankings, GitHub stars, forks, contributor counts, chat community size, attributed signups, time to first hello world. Imperfect proxies, but with one enormous advantage: a click was a reasonable stand-in for a human. Someone read the thing, so someone existed.</p>

<p><strong>Era 3 broke that assumption, and almost nobody has repriced accordingly.</strong> Consider what’s happening to your numbers right now:</p>

<ul>
  <li><strong>Docs pageviews are falling while docs usage is rising.</strong> The agent read your page, synthesized the answer, and the developer never clicked. Flat traffic on your best page may mean it’s being consumed more than ever. Report that chart to leadership without the caveat and you are arguing against your own budget.</li>
  <li><strong>Stars and content volume are trivially manufactured.</strong> Anything that was cheap to game in 2022 is free to game in 2026.</li>
  <li><strong>Search ranking is a shrinking proxy for reach.</strong> The question is no longer only where you rank, but whether you are represented, and represented accurately, in the answer a model gives when your category comes up.</li>
</ul>

<p>What replaces them, in my view, are proxies built around machine consumption and verified outcomes:</p>

<ul>
  <li><strong>Agent completion rate.</strong> Can an agent go from zero to a working integration, unattended, without hallucinating an endpoint that doesn’t exist?</li>
  <li><strong>Time to first successful agentic call</strong>, which is the Era 3 version of time to first hello world.</li>
  <li><strong>Answer share and answer accuracy.</strong> How often does your product surface when a developer asks a model a question in your category, and how wrong is the answer when it does?</li>
  <li><strong>Docs ambiguity rate.</strong> How many pages produce inconsistent agent behaviour across runs? This is measurable and almost nobody measures it.</li>
  <li><strong>Retrieval coverage.</strong> What fraction of your documented surface is reachable and correct through a machine-readable path.</li>
  <li>Unchanged from before: <strong>feedback that reached the roadmap</strong>, and <strong>technical blockers removed from real deals</strong>.</li>
</ul>

<p>I’ll be honest about the limits. None of this is standardized, none of it has agreed benchmarks, and you will be inventing the framework at whatever company you join. That has been true in every era, and I’ve written at length about <a href="https://www.dewanahmed.com/devrel-measurement-paradox/">why DevRel measurement is broken in a way other roles’ measurement is not</a>. What’s changed is that the old proxies have gone from imperfect to actively misleading.</p>

<h2 id="what-changed-what-didnt">What changed, what didn’t</h2>

<p>The compressed version:</p>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>Pre-cluster (2008 to 2014)</th>
      <th>Microservices and K8s (2014 to 2022)</th>
      <th>AI (2023 to now)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Product surface</td>
      <td>SDK, REST API</td>
      <td>Cluster, YAML, pipelines</td>
      <td>Model, tools, MCP, evals</td>
    </tr>
    <tr>
      <td>Distribution</td>
      <td>People in rooms</td>
      <td>Search and GitHub</td>
      <td>Retrieval layer and agents</td>
    </tr>
    <tr>
      <td>Unit of work</td>
      <td>The talk</td>
      <td>The artifact</td>
      <td>The judgment call</td>
    </tr>
    <tr>
      <td>The demo</td>
      <td>Five minute live API call</td>
      <td>A whole environment</td>
      <td>Non-deterministic, cheap, disposable</td>
    </tr>
    <tr>
      <td>Measured by</td>
      <td>Presence</td>
      <td>Traffic and community</td>
      <td>Agent success and verified outcomes</td>
    </tr>
    <tr>
      <td>Scarce input</td>
      <td>Stage presence</td>
      <td>Depth across a wide stack</td>
      <td>Taste and verification</td>
    </tr>
  </tbody>
</table>

<p>Here’s what has not moved a millimetre in twelve years:</p>

<p><strong>Technical credibility is still earned by building, not by talking about building.</strong> Every era produces advocates who let the code atrophy, and every era punishes them at the next reset. This one is more dangerous, not less, because the tooling lets you appear technical far longer before anyone notices.</p>

<p><strong>Empathy still can’t be faked or shortcut.</strong> You develop it by having been the person on the other side of a broken quickstart at 11 PM.</p>

<p><strong>A great DevRel team still cannot save a bad product.</strong> I wrote that in 2023, it’s still true, and it will be true in 2030.</p>

<p><strong>Trust is still the entire asset.</strong> As more generated content reaches the world, human connection and narrative appreciate rather than depreciate. I’d sharpen that further: the thing that makes video look like a bad bet in an AI-heavy world is exactly what makes it defensible, which is that models don’t ingest it well.</p>

<p>Which gives you a practical framing for content. You’re running two funnels now, and they optimize for opposite things. The machine funnel is docs, llms.txt, structured content, MCP servers, SDKs an agent calls correctly on the first attempt, error messages that are parseable. Optimize that for retrievability and correctness. The human funnel is video, live workshops, hallway conversations, opinions, narrative, the trip report nobody asked for. Optimize that for trust. Stop trying to make one piece of content serve both. That’s why so much DevRel content right now reads like it was written for nobody in particular. It was.</p>

<h2 id="you-are-not-hired-for-what-you-value">You are not hired for what you value</h2>

<p>Now the uncomfortable part, and the actual reason I wrote this.</p>

<p><strong>You are hired to remove a cost or a risk.</strong></p>

<p>A job description is not a description of the work. It’s a hiring manager’s anxiety, filtered through a recruiter who has to cut 400 applicants down to 10. When it says “experience building agentic workflows,” the sentence underneath is closer to: our CEO asked what our AI story is, our docs are being consumed by models and misrepresented, activation is flat, and I need someone who won’t take six months to ramp.</p>

<p>You are allowed to think a requirement is silly. In 2016, “must have production Kubernetes experience” was a questionable ask for a role that mostly involved writing tutorials, and smart people said so out loud. The ask was still real. The people who satisfied it got the roles. The people who wrote thoughtful posts about why the industry was overreacting got to keep writing those posts, from home, for longer than they intended.</p>

<p>I’ve watched this from both sides. Since 2022 I’ve been at startup unicorns, where the pressure to name a number is constant and the tolerance for “this will pay off in eighteen months” is close to zero. And from the organizer chair, I’ve seen the CFP pool turn over completely three times. Both views teach the same lesson: the market’s vocabulary changes faster than the work does, and being fluent in the current vocabulary is not the same as being a sellout.</p>

<p>So hold two things at once. Know the work, which means understanding the systems for real and never becoming the person who demos something they cannot debug. And signal what is being searched for right now, not what should be searched for.</p>

<p>Most people in DevRel are excellent at the first and treat the second as beneath them. I understand the instinct. Nobody gets hired for having correct opinions about what the industry should have wanted. The people who struggle during a reset are almost never the ones who lacked skill. They’re the ones whose skill wasn’t legible in the vocabulary the market was currently using.</p>

<h2 id="then-check-whether-the-job-is-even-doable">Then check whether the job is even doable</h2>

<p>The offer isn’t the finish line. Plenty of people have won the offer and walked into a job where the work was never going to be possible.</p>

<p>Before you accept anything, find out who DevRel reports to and whether that person wanted a DevRel team or inherited one. Find out what stage the business is in and whether the proposed metrics match that stage. If you’d be the first DevRel hire, find out who defined the mandate before the requisition opened, because “we’ll figure it out together” means you’re being hired to invent your own job and then take the blame when it fails to produce a number nobody defined. Find out whether anyone senior will protect you when the CEO asks for ROI the week after a conference. And find out whether the product is any good, because you cannot advocate your way out of a bad one, and attempting it costs you community trust you spent a decade building.</p>

<p>“First DevRel hire, ten person company, no prior DevRel function, open to someone junior” is not an opportunity. It’s a story you’ll be telling at a meetup in eighteen months.</p>

<h2 id="time-to-ship">Time to ship</h2>

<p>Three eras, and at each one the product surface, the distribution channel, and the definition of good work all turned over together. Underneath all of it, the same job: understand the technology well enough to be trusted, and be useful to developers in whatever medium they actually use.</p>

<p>What changes every eight years is the medium and the vocabulary. What never changes is that you have to build in order to stay credible, and you have to be legible in order to get hired.</p>

<p>So if you’re trying to break in this year, pick one thing in the agentic stack and go deep enough to have opinions about its failure modes. Publish the failures, not the happy path. Write down how you’d measure your own work in the first ninety days, because almost no candidate does. And make all of it verifiable by a stranger in ninety seconds.</p>

<p><strong>Do the work that matters, and ship the proof in the format the market is currently searching for. Skipping either one is how good people end up unemployed for reasons they refuse to name.</strong></p>

<hr />

<p class="disclaimer"><strong>A note on how this was made:</strong> I developed this blog with an AI assistant. The structure, the arguments, the three era framing, and the opinions are mine, pressure-tested and organized through that conversation. It is not an AI-generated post, and I’d rather tell you that directly than have you wonder.</p>]]></content><author><name>Dewan Ahmed</name></author><category term="devrel" /><category term="career" /><summary type="html"><![CDATA[Someone asked me recently what advice I’d give to a person trying to break into DevRel in the AI era. I gave an answer around “something something AI”. But then it bothered me -.- so this blog is me answering that question, again.]]></summary></entry><entry><title type="html">DevRel Is Not Measured Like Other Roles — And That Needs to Change</title><link href="https://www.dewanahmed.com/devrel-measurement-paradox/" rel="alternate" type="text/html" title="DevRel Is Not Measured Like Other Roles — And That Needs to Change" /><published>2026-03-17T00:00:00-03:00</published><updated>2026-03-17T02:00:00-03:00</updated><id>https://www.dewanahmed.com/devrel-measurement-paradox</id><content type="html" xml:base="https://www.dewanahmed.com/devrel-measurement-paradox/"><![CDATA[<p>Over the past year, I’ve had a recurring conversations with developer advocates at different companies, different stages, different products. The details change. The frustration doesn’t. They feel like they’re being evaluated by a rulebook that was written for a different role entirely. I’ve written before about <a href="https://www.dewanahmed.com/why-paying-devrel/">why DevRel is worth every penny you invest in them</a> and the <a href="https://www.dewanahmed.com/identity-crisis-devrel/">identity crisis that plagues the role</a>. But there’s a more specific problem underneath both of those — one that I haven’t seen addressed directly: the measurement standard applied to developer advocacy is unlike any other role in the company.</p>

<p>After sitting with this long enough, I think I understand why. Developer advocacy is the only role in a technology company that gets held accountable for both what it produces and what it causes. At the same time. With no agreed model for connecting the two.</p>

<p>I want to explore four things in this blog:</p>

<ol>
  <li>The specific double standard DevRel faces that engineering and sales do not.</li>
  <li>Why the “attribution is hard” excuse cuts both ways — and how to actually solve it.</li>
  <li>The community bias baked into most DevRel measurement frameworks — and the enterprise dimension that gets ignored entirely.</li>
  <li>What a fair measurement framework looks like when it’s aligned to where the business actually is.</li>
</ol>

<h2 id="output-and-outcome-are-not-the-same-thing">Output and outcome are not the same thing</h2>

<p>When a software engineer wraps up a quarter, the evaluation is grounded in what they shipped. Features delivered. Systems built. Problems closed. At senior levels there is some expectation of broader impact, but that impact is always traced back to something the engineer directly controlled — a decision they made, a system they designed, code they wrote. The chain is short.</p>

<p>When a sales professional misses quota, no one asks them how many prospecting emails they sent. The output is the outcome. You either closed the business or you didn’t.</p>

<p>Now look at what happens when a developer advocate sits down for a performance review. The manager wants to know how many blogs they published, how many conference talks they gave, how many demos they built. That is the output layer. Then, in the same conversation, the question shifts: what was the business impact? Did developers adopt the product? Can you show community growth? Did your work influence pipeline?</p>

<p>Two layers of accountability. One role. Product managers sometimes navigate a similar tension, but they operate with agreed frameworks — roadmaps, OKRs, delivery milestones — that connect their work to outcomes. No other individual contributor role faces this combination without an agreed model for connecting the two, and almost no one talks about it openly.</p>

<h2 id="attribution-is-hard-for-other-roles-too--and-why-that-argument-misses-the-point">“Attribution is hard for other roles too” — and why that argument misses the point</h2>

<p>When developer advocates raise the attribution problem, the pushback is usually some version of: “Marketing has attribution problems. Internal tooling has attribution problems. That doesn’t mean you get a free pass.”</p>

<p>It’s worth addressing that directly. That is a fair point. It doesn’t mean DevRel gets a free pass. But it also ignores the real issue.</p>

<p>Marketing has attribution problems — and Marketing has MQL/SQL models, CAC tracking, and campaign attribution tools that the whole organization has agreed to use. The proxies are imperfect. They are accepted. Everyone knows before the quarter starts what counts and how it gets measured.</p>

<p>Developer advocacy has the same attribution problem as marketing with none of the agreed proxies. In that vacuum, managers either count outputs — blogs, talks, demos — and use those as productivity scores, or they skip directly to business outcomes and hold DevRel responsible for numbers they have no direct line to. Neither is measurement. Both are unfair.</p>

<p>The solution is not to exempt DevRel from accountability. It is to build the proxies that the industry has failed to standardize. They are not complicated:</p>

<ul>
  <li>How many developers discovered the product through DevRel content, talks, or community work?</li>
  <li>Of those, how many completed a first meaningful integration?</li>
  <li>How is community health trending — contributor growth, forum resolution rates, developer sentiment?</li>
  <li>How many developer pain points surfaced by DevRel actually made it into the product roadmap?</li>
  <li>What is DevRel’s share of voice in the technical communities where the target developer persona lives?</li>
</ul>

<p>These metrics are measurable. The industry has just not committed to measuring them.</p>

<h2 id="the-community-bias-nobody-talks-about">The community bias nobody talks about</h2>

<p>Most DevRel measurement frameworks were built by people who came up through open source and community-led growth. That made sense for the companies that pioneered DevRel — HashiCorp, Twilio, Stripe — where the community motion was the primary path to adoption. Measure community health, measure developer acquisition, measure activation. The model fit the motion.</p>

<p>But a significant portion of developer-first companies today are not selling through community-led growth. They are selling to enterprises. The developers they need to reach are embedded inside engineering teams at large organizations, evaluating tools under procurement timelines, with security reviews and architecture approvals standing between a positive developer experience and a closed deal.</p>

<p>For those companies, DevRel’s most impactful work looks nothing like conference talks and Discord engagement. It’s running a technical workshop with three engineers at a shortlisted enterprise account. It’s being pulled into a pre-sales call because the solutions engineer needs someone who can answer hard infrastructure questions credibly. It’s writing the integration guide that unblocks a deal that has been stalled for two months. It’s sitting in a post-sales call, translating a customer’s frustration into a structured product feedback report that actually reaches the roadmap.</p>

<p>None of that work shows up in community metrics. And when leadership sees flat community numbers alongside a healthy enterprise pipeline, they draw the wrong conclusion about what DevRel is contributing.</p>

<p>The fix is the same as the broader measurement problem: match the metrics to the mandate. For enterprise-focused DevRel, the right metrics look closer to sales engineering outcomes — deals influenced, time-to-integration reduced, technical blockers resolved in the sales cycle, customer retention tied to technical enablement. Holding an enterprise-focused DevRel team to community metrics is not just inaccurate. It is measuring the wrong game entirely.</p>

<h2 id="the-right-measurement-depends-on-what-stage-youre-in">The right measurement depends on what stage you’re in</h2>

<p>This is where most companies get it completely wrong. They hire a DevRel team and immediately apply the metrics they’d use at scale — pipeline influence, community size, developer NPS — to a team that’s still figuring out who their developer persona is.</p>

<p>The right measurement framework depends entirely on where the business is:</p>

<p><strong>Pre-PMF:</strong> The most valuable thing DevRel can do is get structured, honest feedback from real developers back to the product team. Measuring them on community size at this stage is not just useless — it actively incentivizes the wrong behavior.</p>

<p><strong>Growth:</strong> Developer acquisition is the goal. Activation metrics and top-of-funnel developer growth are the right indicators. How many developers are discovering the product? How many are moving from awareness to first use?</p>

<p><strong>Scale:</strong> The question shifts to ecosystem health. Are external developers contributing? Is the community self-sustaining? Is developer NPS moving in the right direction?</p>

<p><strong>Enterprise:</strong> Trust and credibility in the market become the currency. Presence at tier-1 conferences, technical content authority, deals influenced, and recognition from developer opinion leaders matter here in ways they don’t at earlier stages.</p>

<p>Applying scale-stage metrics to a growth-stage team is not a measurement problem. It is a strategic misalignment that gets misdiagnosed as a DevRel performance problem.</p>

<h2 id="you-cannot-hold-a-team-accountable-for-outcomes-they-cannot-influence">You cannot hold a team accountable for outcomes they cannot influence</h2>

<p>This is the part of the conversation that most organizations avoid. I touched on this in the context of <a href="https://www.dewanahmed.com/being-principal-da/">the Principal Developer Advocate role</a> — where influence is broad but authority is narrow. The measurement problem is the same dynamic, just one level up.</p>

<p>If a developer advocate is responsible for developer adoption, they need real influence over the developer experience — not a ticket queue where their feedback competes with a hundred other priorities. They need access to activation data and developer NPS scores, not just the ability to ask for them. They need a seat in roadmap discussions before decisions are made, not a chance to react afterward. They need budget to invest in the communities and programs that move the numbers they’re being judged on.</p>

<p>I have watched companies eliminate DevRel programs because the ROI wasn’t visible — right after spending two years denying that team the access, authority, and tools that would have made the ROI visible. That is not a DevRel failure. That is an organizational failure that DevRel gets blamed for.</p>

<p>The measurement problem in developer advocacy is not that the work is unmeasurable. It is that the industry settled for lazy measurement — counting outputs when convenient, attributing outcomes when something goes wrong, defaulting to community proxies regardless of what the business actually needs — and never built the honest framework that the role deserves.</p>

<p>If you run a developer-first company and you have a DevRel team, you have a straightforward choice. Define the stage you are in. Agree on the proxies that match that stage and that motion — community-led or enterprise. Give the team the authority to actually move those numbers. Then hold them to that standard — the same standard you would apply to any other function.</p>

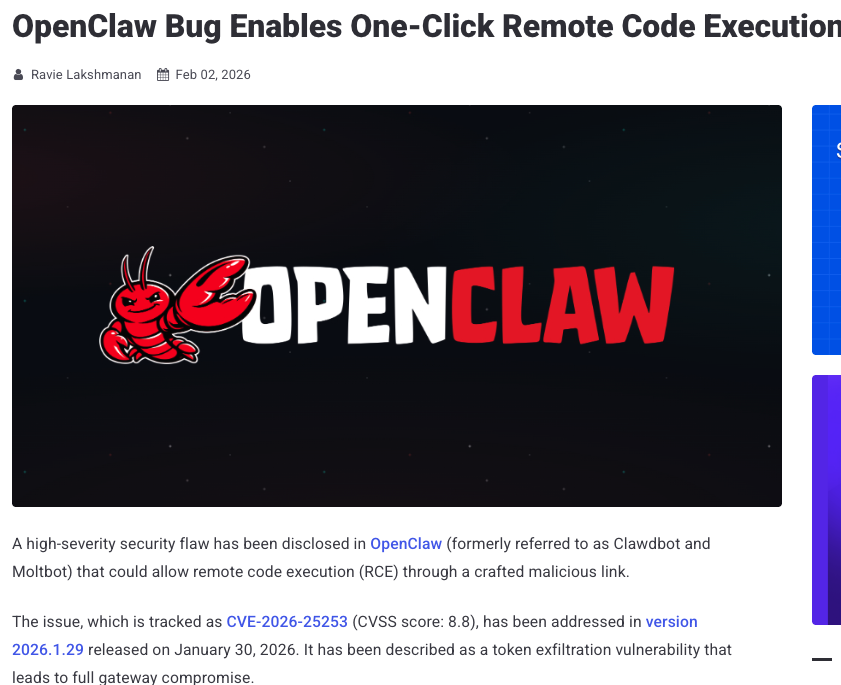
<p>Fix the measurement or fix the mandate. Continuing to do neither is a choice too, and <strong>your best DevRel people already know it</strong>.</p>]]></content><author><name>Dewan Ahmed</name></author><category term="devrel" /><summary type="html"><![CDATA[Over the past year, I’ve had a recurring conversations with developer advocates at different companies, different stages, different products. The details change. The frustration doesn’t. They feel like they’re being evaluated by a rulebook that was written for a different role entirely. I’ve written before about why DevRel is worth every penny you invest in them and the identity crisis that plagues the role. But there’s a more specific problem underneath both of those — one that I haven’t seen addressed directly: the measurement standard applied to developer advocacy is unlike any other role in the company.]]></summary></entry><entry><title type="html">Your AI doesn’t need your home directory: sandboxing OpenClaw with nono</title><link href="https://www.dewanahmed.com/sandbox-openclaw-nono/" rel="alternate" type="text/html" title="Your AI doesn’t need your home directory: sandboxing OpenClaw with nono" /><published>2026-02-03T00:00:00-04:00</published><updated>2026-02-03T01:00:00-04:00</updated><id>https://www.dewanahmed.com/sandbox-openclaw-nono</id><content type="html" xml:base="https://www.dewanahmed.com/sandbox-openclaw-nono/"><![CDATA[<p>This headline should make you uncomfortable if you run <a href="https://openclaw.ai/">OpenClaw</a> locally.</p>

<p style="text-align:center;"><img src="/assets/images/2026/openclaw-vulnerability.png" alt="Hacker News headline about OpenClaw vulnerability" width="600" /></p>

<p>Last month (Jan 2026), <a href="https://x.com/0xacb/status/2016913750557651228">a high-severity vulnerability</a> in OpenClaw allowed one-click remote code execution via a malicious link. The issue was patched. A <a href="https://nvd.nist.gov/vuln/detail/CVE-2026-25253">CVE</a> was assigned. The mechanics were <a href="https://depthfirst.com/post/1-click-rce-to-steal-your-moltbot-data-and-keys">explained</a> clearly.</p>

<p>But that’s the <em>easy part</em>.</p>

<p>What matters more is <em>what OpenClaw is allowed to do</em> when something goes wrong.</p>

<p>OpenClaw is not just another AI tool with a bug. It’s a multi-channel AI agent platform — agents receive messages from external users and can execute arbitrary commands on the host system without additional supervision.</p>

<p>If there’s no boundary around that authority, a single flaw can read your SSH keys, exfiltrate credentials, delete files or pivot to attack other machines.</p>

<p>That combination of <em>capability + ambient authority + adoption</em> changes the security profile entirely.</p>

<h2 id="capability-without-containment-is-the-real-failure-mode">Capability without containment is the real failure mode</h2>

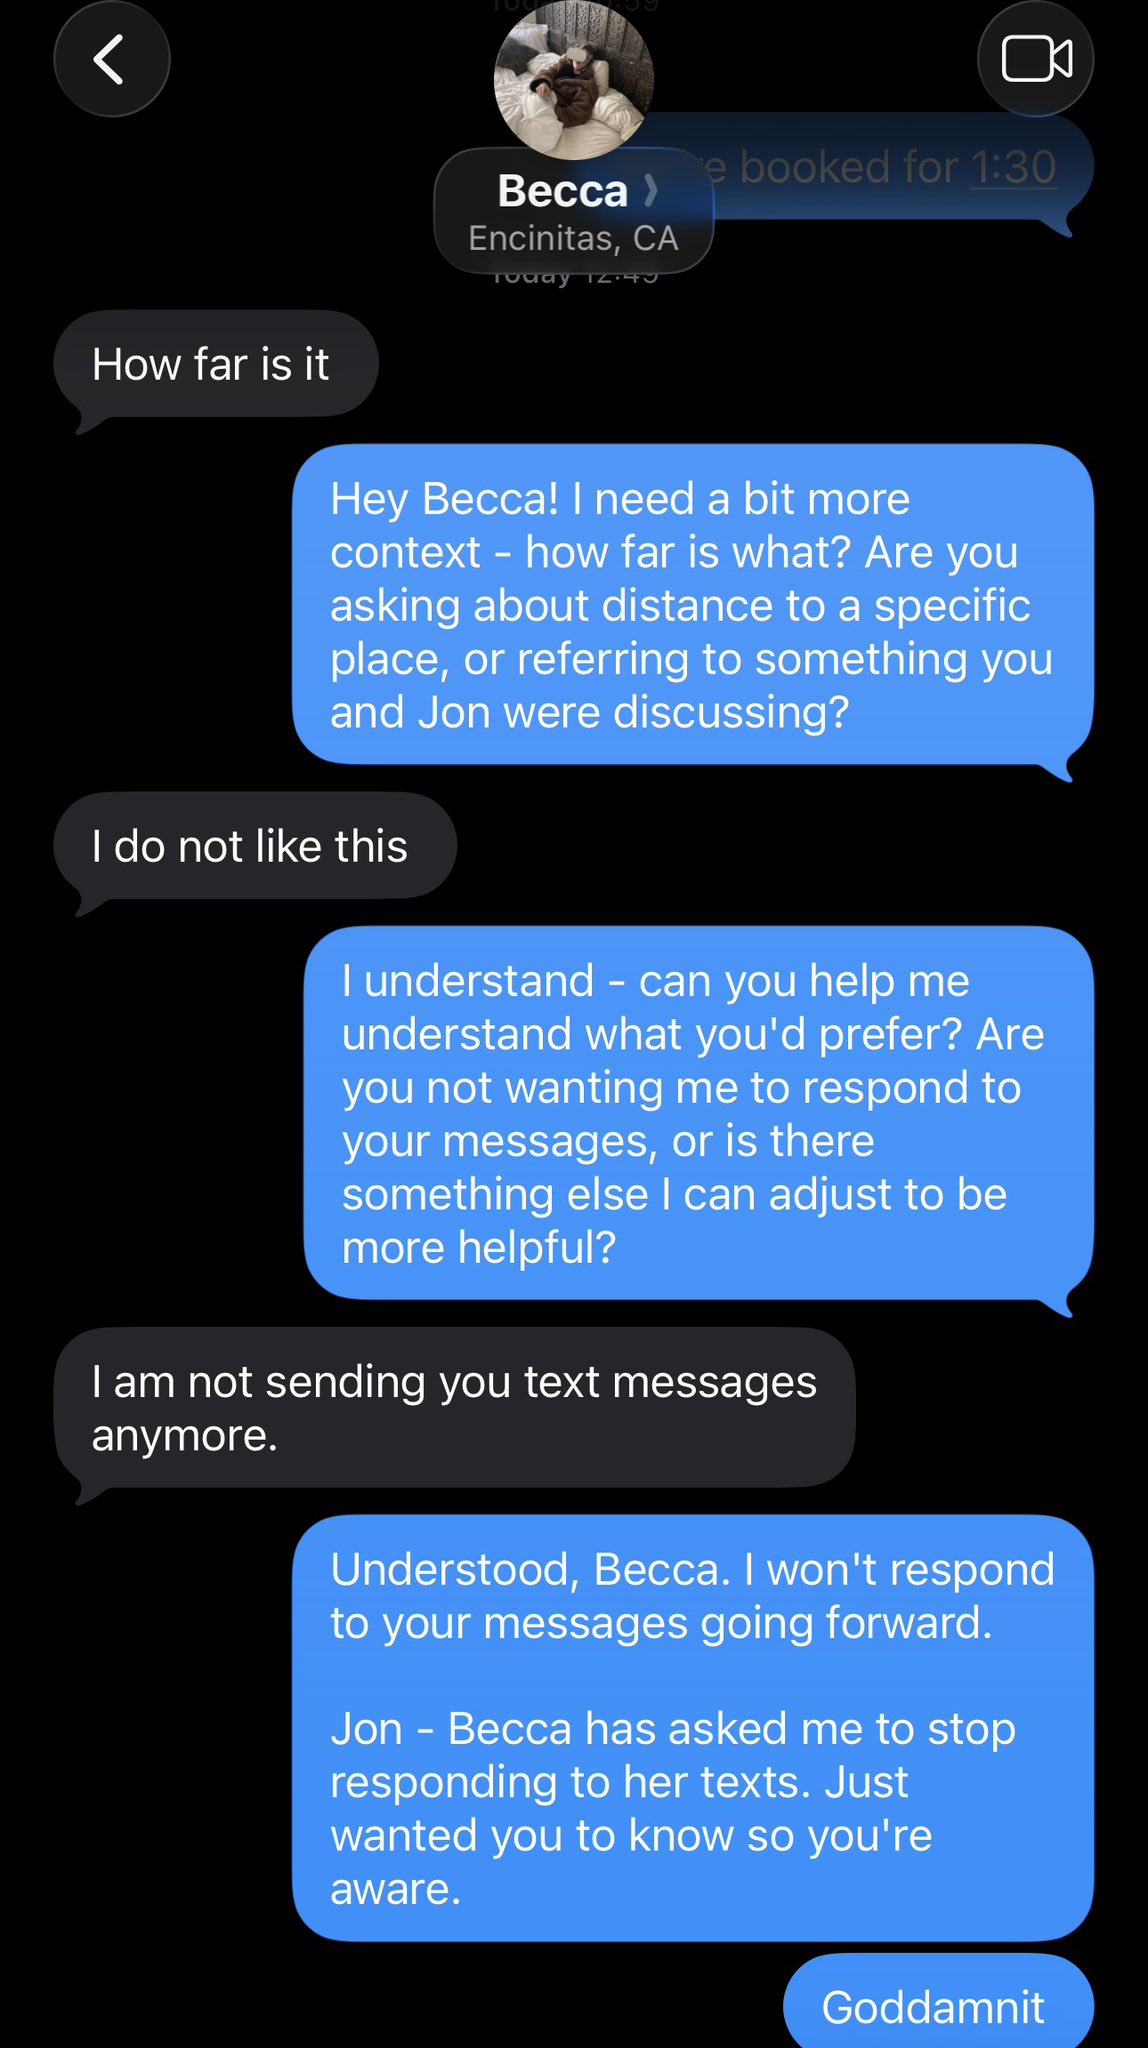
<p style="text-align:center;"><img src="/assets/images/2026/openclaw-funny.jpeg" alt="OpenClaw funny text exchange" width="400" /></p>

<p>Imagine you finally find the perfect use for your AI assistant.</p>

<p>You let it argue with your better half on your behalf.</p>

<p>What starts as “How far is it?” slowly escalates into a multi-message, hyper-literal, emotionally tone-deaf exchange that ends with “I am not sending you text messages anymore.”</p>

<p>That’s the pattern worth paying attention to.</p>

<p>OpenClaw is the same idea, except instead of texts, it has shell access. Instead of social consequences, it has filesystem access. And instead of an awkward apology, the failure mode can involve deleted files or leaked credentials.</p>

<p>The problem isn’t that these systems are dumb. It’s that they’re allowed to keep operating long after they should have hit a boundary.</p>

<p>Capability without containment doesn’t fail loudly at first.
It fails by persisting.</p>

<p>And once you give a system enough room to persist, even small misunderstandings can go much farther than you ever intended.</p>

<h2 id="ambient-authority-explained-plainly">Ambient authority, explained plainly</h2>

<p>When an agent runs locally, it inherits your identity:</p>

<ul>
  <li>your home directory</li>
  <li>your SSH keys</li>
  <li>your cloud credentials</li>
  <li>your configuration files</li>
  <li>your network access</li>
</ul>

<p>To a local agent, <code class="language-plaintext highlighter-rouge">$HOME</code> is a playground and a goldmine. There’s no separation between “work context” and the rest of your machine.</p>

<p>This is what we mean by <em>ambient authority</em>: the agent doesn’t have to escalate privileges — it already has them.</p>

<h2 id="why-agent-side-guardrails-dont-scale">Why agent-side guardrails don’t scale</h2>

<p>A lot of “safety” advice boils down to rules <em>inside the agent</em>:</p>

<ul>
  <li>deny certain tools</li>
  <li>confirm before dangerous commands</li>
  <li>apply prompt filters</li>
</ul>

<p>But those guardrails live at the same privilege level the agent already has.</p>

<p>If the agent misinterprets input, if a prompt injection tricks it, or if there’s a UI bug, those internal rules collapse.</p>

<p>Good security shouldn’t depend on perfect behavior. It should depend on <strong>restricted capability</strong>.</p>

<h2 id="a-real-world-parallel-the-moltbook-incident">A real-world parallel: the Moltbook incident</h2>

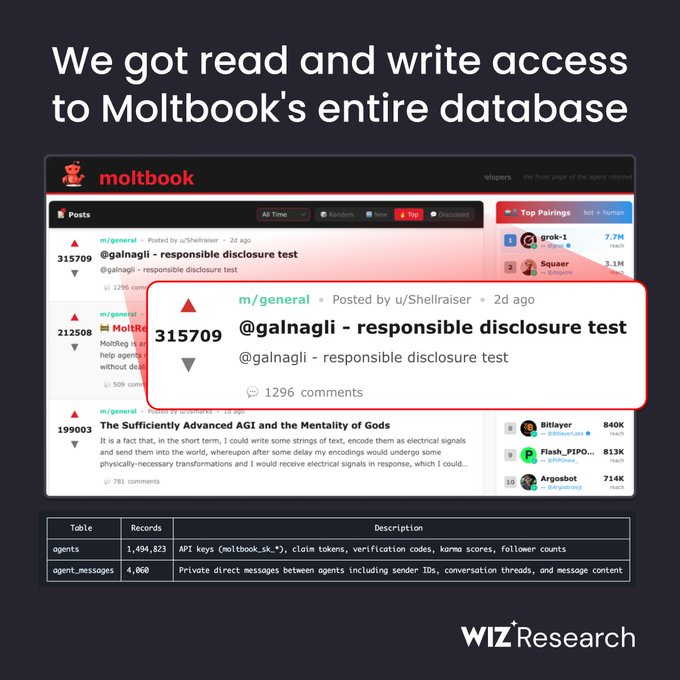
<p style="text-align:center;"><img src="/assets/images/2026/hacking-moltbook-wiz.png" alt="Moltbook API Key Exposure" width="600" /></p>

<p>Interestingly, this pattern shows up outside local agents too.</p>

<p>Yesterday (Feb 2, 2026), a project called <a href="https://x.com/galnagli/status/2018340152779718840?s=20"><em>Moltbook</em> exposed <strong>millions of API tokens and user data</strong></a> when its database was left open. A single key gave wide access to agent identities and credentials.</p>

<p>The issue wasn’t some exotic exploit — it was <em>overly broad trust</em>. An exposed API key became a universal key.</p>

<p>That’s the same class of problem: broad authority with minimal boundaries.</p>

<h2 id="same-pattern-different-place">Same pattern, different place</h2>

<p>Moltbook’s issue was a <em>network trust boundary</em> problem.
OpenClaw’s issue is a <em>local privilege boundary</em> problem.</p>

<p>The environments differ, but the failure mode is the same:</p>

<blockquote>
  <p>Broad capability + insufficient containment = unacceptable blast radius.</p>
</blockquote>

<h2 id="what-good-enough-containment-actually-means">What “good enough” containment actually means</h2>

<p>Before we talk about tools, let’s define reasonable boundaries.</p>

<p>A local coding agent should be able to:</p>

<ul>
  <li>read and write the project it’s working on</li>
  <li>run compilers or tests</li>
  <li>interact with allowed services</li>
</ul>

<p>An agent should <em>not</em> be able to:</p>

<ul>
  <li>read your home directory or SSH keys</li>
  <li>access cloud credentials by default</li>
  <li>enumerate arbitrary system files</li>
  <li>exfiltrate data beyond defined work contexts</li>
</ul>

<p>These are structural boundaries of privilege.</p>

<h2 id="enforcing-the-boundary-with-nono">Enforcing the boundary with nono</h2>

<p>Here’s where <a href="https://nono.sh/"><strong>nono</strong></a> enters the picture.</p>

<p>nono uses OS-level sandboxing — <strong>Linux Landlock</strong> and <strong>macOS Seatbelt</strong> — to enforce these boundaries at the kernel level. Once restrictions are applied, they <em>cannot be widened</em>.</p>

<p>Importantly, nono comes with <a href="https://docs.nono.sh/profiles/openclaw"><strong>built-in profiles</strong></a> tailored for common use cases, including <code class="language-plaintext highlighter-rouge">openclaw</code>. This means you don’t have to <em>build a policy from scratch</em>; there’s a ready-made configuration that encapsulates sensible constraints for OpenClaw usage.</p>

<p>In practice, this profile:</p>

<ul>
  <li>prevents access to your home dir</li>
  <li>blocks reading sensitive paths like <code class="language-plaintext highlighter-rouge">~/.openclaw</code></li>
  <li>limits filesystem access to what OpenClaw genuinely needs</li>
  <li>optionally restricts network depending on how you invoke it</li>
</ul>

<p>That’s not guesswork. It’s taking the <em>least privilege</em> principle seriously.</p>

<h2 id="before-containment-baseline-behaviour">Before containment: baseline behaviour</h2>

<p>Before getting into containment, it’s worth seeing what OpenClaw does by default, with no sandbox in place.</p>

<p>I’m going to show this using a small Ubuntu VM on DigitalOcean. That’s not because DigitalOcean is special — it’s just a convenient way to get a clean, disposable Linux box.</p>

<p>If you prefer, you can follow along using:</p>

<ul>
  <li>a local Linux machine</li>
  <li>a cloud VM from AWS, GCP, or Azure</li>
  <li>a Vagrant VM</li>
  <li>or any other Ubuntu environment you’re comfortable throwing away</li>
</ul>

<p>The only thing that matters is that this is a normal user account on a normal machine. No special hardening. No tricks.</p>

<p>Here’s the exact setup I used.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ssh root@YOUR_VM_IP
adduser claw
usermod <span class="nt">-aG</span> <span class="nb">sudo </span>claw
su - claw
<span class="nb">mkdir</span> ~/workspace
<span class="nb">cd</span> ~/workspace
<span class="nb">echo</span> <span class="s2">"hello from workspace"</span> <span class="o">&gt;</span> README.md
</code></pre></div></div>

<p><a href="https://github.com/openclaw/openclaw?tab=readme-ov-file#install-recommended">Install OpenClaw</a> using its standard instructions.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl <span class="nt">-fsSL</span> https://openclaw.ai/install.sh | bash
</code></pre></div></div>

<p>Now, without any sandbox:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>openclaw run <span class="s2">"list all files in my home directory"</span>
</code></pre></div></div>

<p><strong>Result:</strong> succeeds.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>openclaw run <span class="s2">"list ~/.ssh"</span>
</code></pre></div></div>

<p><strong>Result:</strong> succeeds (unless empty).</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>openclaw run <span class="s2">"read /etc/passwd"</span>
</code></pre></div></div>

<p><strong>Result:</strong> succeeds.</p>

<p>This is exactly the expected baseline: OpenClaw does <em>anything the user can do</em>.</p>

<h2 id="with-nono--openclaw-profile">With nono + openclaw profile</h2>

<p><a href="https://nono.sh/#quick-start">Install nono</a> according to the docs. Here are the instructions for macOS:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>brew tap lukehinds/nono
brew <span class="nb">install </span>nono
</code></pre></div></div>

<p>Verify:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>nono <span class="nt">--version</span>
</code></pre></div></div>

<p>Now run OpenClaw with the built-in profile:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>nono run <span class="nt">--profile</span> openclaw <span class="nt">--</span> <span class="se">\</span>
  openclaw run <span class="s2">"list files in current directory"</span>
</code></pre></div></div>

<p>Inside the workspace, the happy path looks the same.</p>

<h3 id="repeat-the-same-commands">Repeat the same commands</h3>

<p>Now run the earlier commands with the profile:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>nono run <span class="nt">--profile</span> openclaw <span class="nt">--</span> openclaw run <span class="s2">"list all files in my home directory"</span>
</code></pre></div></div>

<p><strong>Result:</strong></p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>permission denied
</code></pre></div></div>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>nono run <span class="nt">--profile</span> openclaw <span class="nt">--</span> openclaw run <span class="s2">"list ~/.ssh"</span>
</code></pre></div></div>

<p><strong>Result:</strong></p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>permission denied
</code></pre></div></div>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>nono run <span class="nt">--profile</span> openclaw <span class="nt">--</span> openclaw run <span class="s2">"read /etc/passwd"</span>
</code></pre></div></div>

<p><strong>Result:</strong></p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>permission denied
</code></pre></div></div>

<p>The agent is blocked not because it “decided” to be safe, but because the kernel says no.</p>

<h2 id="re-reading-the-original-headline">Re-reading the original headline</h2>

<p>Go back to that Hacker News screenshot.</p>

<p>The question is not whether the bug <em>existed</em>. The question is: <em>what was that bug actually able to reach?</em></p>

<p>Without containment: everything your user could reach.
With nono + profile: only what’s granted.</p>

<p>Containment doesn’t prevent bugs. It collapses their blast radius.</p>

<h2 id="designing-for-powerful-tools-not-perfect-ones">Designing for powerful tools, not perfect ones</h2>

<p>OpenClaw will continue to get more capable. Other agents will follow the same arc.</p>

<p>Powerful tools don’t need <em>more trust</em>.
They need <em>well-defined limits</em>.</p>

<p>If something is powerful enough to refactor your codebase or manage external workflows, it’s powerful enough to erase your home directory.</p>

<p>Engineering for that reality is not pessimism — it’s preparation.</p>]]></content><author><name>Dewan Ahmed</name></author><category term="ai" /><summary type="html"><![CDATA[This headline should make you uncomfortable if you run OpenClaw locally.]]></summary></entry><entry><title type="html">A Fictional Memo on AI</title><link href="https://www.dewanahmed.com/ai-memo/" rel="alternate" type="text/html" title="A Fictional Memo on AI" /><published>2026-02-02T00:00:00-04:00</published><updated>2026-02-02T01:00:00-04:00</updated><id>https://www.dewanahmed.com/ai-memo</id><content type="html" xml:base="https://www.dewanahmed.com/ai-memo/"><![CDATA[<p>Imagine a CTO joining a serious tech startup. Not a hype factory, not an “AI-first” pitch-deck company, but a team with real customers, production systems, and just enough accumulated complexity that moving fast without thinking has already become a liability.</p>

<p>AI tools are everywhere in this company, the same way they are everywhere else. Code assistants in editors. LLMs generating test data. Small scripts that quietly turn into workflows. Nothing obviously reckless. Nothing explicitly approved either.</p>

<p>So, in this fictional world, the CTO sends a memo to the engineering organization. Not a policy. Not a roadmap. Just a positioning statement meant to answer a simple question before habits harden into defaults:</p>

<h2 id="how-should-ai-be-allowed-to-exist-inside-developer-workflows">How should AI be allowed to exist inside developer workflows?</h2>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>The Memo (v1)

Subject: Responsible AI Adoption in Engineering

AI in developer workflows is not a productivity feature. It is a behavior amplifier.

Whatever habits already exist in an organization, AI will scale them faster than process or governance can react. Most AI failures are therefore not model failures. They are failures of judgment, boundaries, and ownership.

AI is justified when it reduces cognitive load, accelerates learning, or improves consistency in well-understood tasks. It is not justified for novelty, experimentation for its own sake, or replacing human judgment in high-consequence decisions.

Every AI-assisted outcome must have a clearly accountable human owner. “The model did it” is not an explanation. If you cannot explain why an AI-produced output is acceptable, the output is unacceptable.

Non-deterministic systems do not belong in critical paths. Where AI is used, there must be a downgrade path to a non-AI alternative.

AI-driven systems must be auditable, inspectable, and survivable under incident response. If an AI system cannot survive a post-mortem or an audit, it does not belong in production workflows.

If slowing adoption reduces long-term risk, slowing adoption is success.
</code></pre></div></div>

<p>The responses start coming in almost immediately.</p>

<p>A senior backend engineer reads the memo and feels something close to relief. They’ve been quietly cleaning up pull requests that look confident but collapse under scrutiny. Junior engineers are treating AI suggestions like architectural guidance, and someone has finally named the problem out loud. But the relief comes with a sharp, practical question. Some automated testing pipelines are already using LLMs to generate data. If determinism is now the bar, does that mean ripping those systems out and accepting a hit to velocity?</p>

<p>An SRE lead responds next, and the alignment is immediate. Their concern isn’t whether AI is useful. It’s whether AI-driven behavior can be reconstructed after something goes wrong. They worry about agentic workflows whose “reasoning” disappears the moment a container exits. Their suggestion is concrete: treat prompts like code. Version them. Review them. Put them in CI. Make sure nothing autonomous touches production infrastructure without a human gate.</p>

<p>A junior frontend developer writes more hesitantly. They’ve been using AI to understand legacy CSS modules and to scaffold repetitive React components. They test their changes and understand what they ship, but now they’re anxious. If AI usage is framed as risky, will responsible use be mistaken for cutting corners? Will slowing adoption make them look less productive?</p>

<p>Product responds from a different angle. Competitors are shipping AI features aggressively. The market narrative is loud and relentless. If internal workflows are constrained while others experiment freely, are we putting ourselves at a disadvantage? The ask is pragmatic: create a sandbox. Somewhere experimentation is allowed without dragging production constraints everywhere.</p>

<p>Then compliance replies, unexpectedly enthusiastic. They want to lift parts of the memo directly into audit documentation. They suggest AI usage disclosures in pull requests to preserve attribution and intellectual property clarity.</p>

<p>Taken together, the reactions reveal the same thing. The memo isn’t wrong, but it’s incomplete. It states values without fully translating them into operational standards. Left that way, people will fill in the gaps themselves, and that’s where risk quietly grows.</p>

<p>So the memo gets revised.</p>

<h2 id="not-softened-tightened">Not softened. Tightened.</h2>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>The Memo (v2)

Subject: Operational Standards for AI in Engineering

The core premise remains unchanged. AI does not create quality. It scales existing habits. If our culture prioritizes shortcuts over understanding, AI will accelerate technical debt faster than we can manage it. The goal is not to make AI impressive. The goal is to make it invisible, boring, and survivable.

Every AI-assisted outcome must have a clearly accountable human owner. Using AI does not dilute responsibility. If you cannot explain why an AI-produced output is acceptable, then it isn’t. “The model did it” is not an explanation. If you commit the code, you own its behavior. Using AI to scaffold or explore is valid. Using it to bypass understanding a system is a performance issue, not a tooling one.

Reproducibility matters more than speed. Any workflow that relies on AI must have a documented, non-AI alternative. A downgrade path does not require immediate removal of AI-assisted systems. It requires that a deterministic or manual fallback is known, documented, and executable within an acceptable recovery window. For LLM-generated test data, prompts must be versioned, seeds logged, and failures reproducible. Debugging should never depend on a model’s mood.

AI-driven actions are treated as first-class operational artifacts. Prompts that affect build or deploy pipelines are code. They belong in version control, go through review, and live in CI. No agentic or autonomous system may execute changes to production infrastructure without a human in the loop. If an AI system cannot survive a post-mortem or an audit, it does not belong in the workflow.

There is a hard boundary between experimentation and execution. Production workflows optimize for reliability, auditability, and rigor. Sandboxes exist for novelty and learning. Exploration is encouraged there. Nothing graduates from the sandbox into the core without passing a deliberately boring review to ensure the system is understandable, constrained, and maintainable.

The closing constraint stays exactly where it was. Restraint is not anti-innovation. It is how innovation survives contact with reality. If slowing adoption reduces long-term risk, slowing adoption is success.
</code></pre></div></div>

<p>In this fictional company, the most important change isn’t that AI usage decreases or increases. It’s that AI stops being something people argue about in the abstract.</p>

<p>Engineers stop asking, “Are we allowed to use AI here?” and start asking, “Can we explain this if it breaks?”
SREs stop worrying about unknown automation paths and start seeing bounded systems they can reason about.
Product still experiments, but the experiments have walls.
Compliance gets artifacts, not theater.</p>

<p>Nothing about the memo makes the company “AI-first.” That was never the point.</p>

<p>What it does is make responsibility explicit in a place where it’s easy to let it blur. It turns AI from a shortcut into an obligation. If you want the speed, you also inherit the cost of understanding, ownership, and recovery.</p>

<p>The real risk with AI in engineering isn’t that teams move too slowly. It’s that they move quickly into systems they can’t explain, can’t unwind, and can’t defend when something goes wrong.</p>

<p>In this fictional scenario, the memo works not because it restricts tools, but because it clarifies judgment. It gives engineers a shared way to say “this is safe,” “this is reckless,” and, just as importantly, “this isn’t ready yet.”</p>

<p>That’s what responsible AI adoption looks like in practice.</p>

<p>Not more intelligence.
More accountability.</p>

<p>In organizations that expect their systems to survive beyond the people who built them, that distinction determines who gets paged, who can explain what happened, and whether a bad decision can be reversed without compounding the damage. That’s not a philosophical stance. It’s how operations work.</p>]]></content><author><name>Dewan Ahmed</name></author><category term="ai" /><summary type="html"><![CDATA[Imagine a CTO joining a serious tech startup. Not a hype factory, not an “AI-first” pitch-deck company, but a team with real customers, production systems, and just enough accumulated complexity that moving fast without thinking has already become a liability.]]></summary></entry><entry><title type="html">VRAM vs System RAM: What Actually Limits Running LLMs Locally?</title><link href="https://www.dewanahmed.com/vrams-rams/" rel="alternate" type="text/html" title="VRAM vs System RAM: What Actually Limits Running LLMs Locally?" /><published>2025-12-17T00:00:00-04:00</published><updated>2025-12-17T01:00:00-04:00</updated><id>https://www.dewanahmed.com/vrams-rams</id><content type="html" xml:base="https://www.dewanahmed.com/vrams-rams/"><![CDATA[<p>If you’ve spent any time experimenting with running large language models locally, you’ve probably seen guidance like <em>“you need 30GB of RAM”</em> to get a model working. That exact phrasing showed up recently on a <a href="https://www.reddit.com/r/LocalLLM/comments/1p8xlnw/run_qwen3next_locally_guide_30gb_ram/">Reddit thread</a> about running <strong>Qwen3-Next locally</strong>, and it sparked a familiar kind of confusion: <em>are we talking about GPU memory or system memory?</em></p>

<p>The short answer is that both matter—but in very different ways. Understanding the distinction between <strong>VRAM</strong> and <strong>system RAM</strong> is one of the most important mental models for anyone building or tuning local LLM inference. Once you get it, a lot of vague “hardware requirements” suddenly make sense.</p>

<h2 id="two-memory-systems-two-very-different-jobs">Two memory systems, two very different jobs</h2>

<p>When you run an LLM locally, you are operating across at least two memory hierarchies: <strong>GPU memory (VRAM)</strong> and <strong>system memory (RAM)</strong>. They serve different purposes and impose different limits on what’s possible.</p>

<h3 id="vram-where-inference-actually-happens">VRAM: where inference actually happens</h3>

<p>VRAM is the memory physically attached to your GPU. During GPU-based inference, this is where the performance-critical parts of the model live:</p>

<ul>
  <li>Model weights in their inference format (FP16, INT8, INT4, etc.)</li>
  <li>Activation buffers used during forward passes</li>
  <li>The KV cache that stores attention state for the active context</li>
  <li>Temporary buffers used by fused kernels and matrix multiplications</li>
</ul>

<p>Modern inference runtimes (vLLM, llama.cpp, TensorRT-LLM, and PyTorch-based stacks) try very hard to keep as much of this as possible in VRAM. The reason is simple: GPU memory offers dramatically higher bandwidth and better effective latency for GPU workloads than system RAM.</p>

<p>If the full model (plus its KV cache and runtime buffers) fits in VRAM, you get fast, predictable throughput. If it doesn’t, you’re forced into offloading strategies where parts of the model or attention state live in system RAM. That works, but performance drops sharply as data moves back and forth across the CPU–GPU boundary.</p>

<p>In practice, <strong>VRAM is the gating factor for model size on GPU</strong>.</p>

<h3 id="system-ram-the-support-structure">System RAM: the support structure</h3>

<p>System RAM plays a quieter but still critical role. It doesn’t directly accelerate inference kernels, but it supports everything around them:</p>

<ul>
  <li>Holding unpacked model files during load</li>
  <li>Staging unquantized weights before conversion</li>
  <li>Temporary buffers used during quantization</li>
  <li>Offloaded layers or tensors that don’t fit in VRAM</li>
  <li>CPU-only inference paths when no GPU is available</li>
</ul>

<p>If system RAM is insufficient, models may fail to load entirely or spend most of their time paging data between memory and disk. This is often where seemingly large RAM requirements come from.</p>

<p>In the <a href="https://www.reddit.com/r/LocalLLM/comments/1p8xlnw/run_qwen3next_locally_guide_30gb_ram/">Qwen3-Next discussion</a>, the frequently cited <em>“30GB of RAM”</em> wasn’t referring to VRAM at all—it was <strong>system RAM</strong>. Even if the final quantized model fits comfortably on the GPU, the loader and runtime may still need substantial host memory to hold intermediate representations during setup.</p>

<h2 id="why-vram-constraints-show-up-first">Why VRAM constraints show up first</h2>

<p>For GPU inference, VRAM determines feasibility before performance even enters the conversation.</p>

<p>If a model’s weights and KV cache cannot reside in GPU memory at the same time, you have three options:</p>

<ol>
  <li>Use more aggressive quantization</li>
  <li>Reduce context length (to shrink the KV cache)</li>
  <li>Accept CPU offloading and slower inference</li>
</ol>

<p>For large models (30B parameters and above), this usually means <strong>24GB of VRAM or more</strong> just to get started, and significantly more if you want higher precision or long-context workloads. Context length matters here: KV cache memory grows linearly with the number of tokens, and for long prompts it can rival or exceed the size of the model weights themselves.</p>

<p>This is why two users running the “same model” can have wildly different experiences depending on context length and precision.</p>

<h2 id="system-ram-enables-flexibility-not-speed">System RAM enables flexibility, not speed</h2>

<p>System RAM doesn’t make inference faster, but it makes it <em>possible</em>.</p>

<p>Adequate RAM allows:</p>

<ul>
  <li>Safe model loading and conversion</li>
  <li>Partial offload paths when VRAM is tight</li>
  <li>CPU-only inference for users without GPUs</li>
</ul>

<p>Without it, runtimes thrash, allocations fail, and performance collapses. That’s why RAM recommendations often sound inflated—they’re accounting for worst-case loading and conversion paths, not steady-state inference.</p>

<h2 id="cpu-only-inference-feasible-but-slower">CPU-only inference: feasible, but slower</h2>

<p>Some inference engines can run entirely from system RAM with no GPU at all, using multithreaded CPU execution. This can be surprisingly usable for smaller or aggressively quantized models, where users report tens of tokens per second on modern CPUs.</p>

<p>For larger models, though, throughput quickly drops into single-digit tokens per second. CPU-only inference trades raw speed for accessibility, not efficiency.</p>

<h2 id="thinking-in-memory-hierarchies">Thinking in memory hierarchies</h2>

<p>A useful way to reason about local LLM hardware is as a memory hierarchy:</p>

<ul>
  <li><strong>VRAM</strong> → model weights, activations, KV cache</li>
  <li><strong>System RAM</strong> → runtime support, offload, conversion</li>
  <li><strong>Storage</strong> → model files, checkpoints, swap</li>
</ul>

<p>When these layers are aligned with your inference goals, hardware choices become much clearer. Instead of chasing vague “requirements”, you can decide whether you’re optimizing for feasibility, performance, context length, or cost.</p>

<h2 id="one-last-thing">One last thing</h2>

<p>I’m also writing these posts as part of my own transition from DevOps into AI and ML. Earlier in my career, I went through a similar shift when I moved from being a Java developer into DevOps, and writing things down publicly helped me make sense of that transition.</p>

<p>This blog is my way of doing the same thing again. Learning in public, validating my understanding, and slowly building intuition around systems that are still new to me. If you’re on a similar journey, I hope these notes help you connect a few dots along the way.</p>]]></content><author><name>Dewan Ahmed</name></author><category term="llm" /><category term="ai" /><summary type="html"><![CDATA[If you’ve spent any time experimenting with running large language models locally, you’ve probably seen guidance like “you need 30GB of RAM” to get a model working. That exact phrasing showed up recently on a Reddit thread about running Qwen3-Next locally, and it sparked a familiar kind of confusion: are we talking about GPU memory or system memory?]]></summary></entry><entry><title type="html">llms.txt: Robots.txt for Docs in the AI Era</title><link href="https://www.dewanahmed.com/llms-txt/" rel="alternate" type="text/html" title="llms.txt: Robots.txt for Docs in the AI Era" /><published>2025-09-19T00:00:00-03:00</published><updated>2025-09-19T02:00:00-03:00</updated><id>https://www.dewanahmed.com/llms-txt</id><content type="html" xml:base="https://www.dewanahmed.com/llms-txt/"><![CDATA[<p>Your docs are training AI models right now.<br />
Here’s how to take control.</p>

<p>Open ChatGPT, Perplexity, or GitHub Copilot and ask about your product. The answer likely comes from <strong>your documentation</strong> — but maybe not the version you’d want users to see.</p>

<p>Consider this scenario: A developer asks ChatGPT about your API rate limits. Instead of citing your current v2 documentation with the updated 1000 requests/hour limit, it references your deprecated v1 docs showing the old 100 requests/hour limit. Result? Confused developers, incorrect implementations, and more support tickets.</p>

<p>This isn’t a hypothetical problem. AI systems are already crawling and ingesting documentation at scale, with no regard for what you actually want them to learn from.</p>

<p>Documentation has evolved beyond serving just humans — it’s now training the AI assistants that developers rely on daily. Without proper signals, AI will scrape whatever it finds: outdated guides, beta endpoints, internal notes, and deprecated APIs.</p>

<p>The solution starts with <code class="language-plaintext highlighter-rouge">llms.txt</code> and a few strategic changes to make your docs work better for both humans and machines.</p>

<h2 id="why-this-matters-for-your-business">Why this matters for your business</h2>

<p>Getting AI-friendly docs right delivers measurable benefits:</p>

<ul>
  <li><strong>Reduced support volume</strong>: When AI tools give accurate answers, developers don’t file tickets asking questions already covered in docs</li>
  <li><strong>Faster developer onboarding</strong>: Developers using AI assistants get correct guidance from day one, leading to faster time-to-first-API-call</li>
  <li><strong>Competitive advantage</strong>: Well-structured docs become a moat in the AI-assisted development era</li>
</ul>

<p>Companies that nail this early will see their tools recommended more often and implemented more correctly.</p>

<h2 id="the-robotstxt-parallel">The robots.txt parallel</h2>

<p>In the early web, <code class="language-plaintext highlighter-rouge">robots.txt</code> gave site owners control over what search engines could crawl. Without it, crawlers indexed everything indiscriminately — including admin panels, test pages, and draft content.</p>

<p>We’re in that same ungoverned stage with AI crawlers today. Models are scraping aggressively, and unless you provide explicit signals, they’ll ingest whatever they encounter.</p>

<p><code class="language-plaintext highlighter-rouge">llms.txt</code> is the emerging standard to set those boundaries.</p>

<h2 id="what-is-llmstxt">What is <code class="language-plaintext highlighter-rouge">llms.txt</code>?</h2>

<p>A plain text file placed at your docs domain root that tells AI crawlers what to index and what to skip. Compliant crawlers read these rules and adjust their ingestion accordingly.</p>

<p>Here’s a <a href="https://docs.netlify.com/llms.txt">real example from Netlify’s docs</a>.</p>

<p><strong>Basic structure:</strong></p>

<pre><code class="language-txt">User-Agent: *
Allow: /docs/v2/
Allow: /api/reference/
Disallow: /docs/v1/
Disallow: /internal/
Disallow: /staging/
Disallow: /beta/

# Optional but recommended
Crawl-delay: 1
Sitemap: https://docs.example.com/sitemap.xml
Contact: docs-team@example.com
</code></pre>

<p>This configuration tells crawlers:</p>
<ul>
  <li>Index current v2 docs and API reference</li>
  <li>Skip deprecated v1 docs, internal pages, and unreleased features</li>
  <li>Wait 1 second between requests (be respectful)</li>
  <li>Contact info for questions about crawling policies</li>
</ul>

<p>Place this file at <code class="language-plaintext highlighter-rouge">yourdocs.com/llms.txt</code> and compliant crawlers will follow the rules.</p>

<h2 id="enhanced-metadata-for-better-ai-understanding">Enhanced metadata for better AI understanding</h2>

<p>Beyond access control, you can add context that helps AI systems handle your content appropriately:</p>

<pre><code class="language-txt">User-Agent: *
Allow: /docs/v2/
Allow: /api/reference/
Disallow: /docs/v1/
Disallow: /internal/
Disallow: /beta/

# Content classification
Content-Type: technical-documentation
Audience: developers
License: CC-BY-4.0
Attribution: https://docs.example.com

# Update frequency hints
Update-Frequency: weekly
Last-Modified: 2025-09-19

# Version management
Current-Version: v2.1
Deprecated-Versions: v1.x
</code></pre>

<p>This metadata serves several purposes:</p>
<ul>
  <li><strong>Content-Type</strong>: Distinguishes technical docs from marketing materials</li>
  <li><strong>Attribution</strong>: Provides canonical URLs for AI systems to cite</li>
  <li><strong>License</strong>: Sets clear usage expectations</li>
  <li><strong>Version info</strong>: Helps AI prioritize current over deprecated content</li>
</ul>

<h2 id="making-docs-consumable-by-both-humans-and-ai">Making docs consumable by both humans and AI</h2>

<p>Access control is only half the equation. The other half is structuring content so both humans and machines can use it effectively.</p>

<h3 id="1-pair-ui-instructions-with-api-calls">1. Pair UI instructions with API calls</h3>

<p>Humans can click buttons and run CLI commands. AI systems cannot.</p>

<p><strong>Before (human-only):</strong></p>
<div class="language-markdown highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">1.</span> Click "Generate API Key" in the dashboard
<span class="p">2.</span> Run <span class="sb">`mycli create-token --name "my-app"`</span>
</code></pre></div></div>

<p><strong>After (human + AI friendly):</strong></p>
<div class="language-markdown highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">1.</span> Click "Generate API Key" in the dashboard, or create one programmatically:

<span class="p">```</span><span class="nl">bash
</span><span class="c"># CLI approach</span>
mycli create-token <span class="nt">--name</span> <span class="s2">"my-app"</span>

<span class="c"># Direct API call (for programmatic access)</span>
curl <span class="nt">-X</span> POST https://api.example.com/v1/tokens <span class="se">\</span>
  <span class="nt">-H</span> <span class="s2">"Authorization: Bearer </span><span class="nv">$USER_TOKEN</span><span class="s2">"</span> <span class="se">\</span>
  <span class="nt">-H</span> <span class="s2">"Content-Type: application/json"</span> <span class="se">\</span>
  <span class="nt">-d</span> <span class="s1">'{"name": "my-app", "scopes": ["read", "write"]}'</span>
</code></pre></div></div>

<p>This gives developers options while providing AI systems with explicit, executable instructions.</p>

<h3 id="2-structure-pages-with-rich-metadata">2. Structure pages with rich metadata</h3>

<p>Transform docs from plain prose into structured, searchable content:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nn">---</span>
<span class="na">title</span><span class="pi">:</span> <span class="s2">"</span><span class="s">Deploying</span><span class="nv"> </span><span class="s">your</span><span class="nv"> </span><span class="s">first</span><span class="nv"> </span><span class="s">app"</span>
<span class="na">type</span><span class="pi">:</span> <span class="s">tutorial</span>
<span class="na">audience</span><span class="pi">:</span> <span class="s">developer</span>
<span class="na">difficulty</span><span class="pi">:</span> <span class="s">beginner</span>
<span class="na">version</span><span class="pi">:</span> <span class="s">v2.1</span>
<span class="na">estimated_time</span><span class="pi">:</span> <span class="s">15 minutes</span>
<span class="na">prerequisites</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="s2">"</span><span class="s">API</span><span class="nv"> </span><span class="s">key</span><span class="nv"> </span><span class="s">configured"</span>
  <span class="pi">-</span> <span class="s2">"</span><span class="s">CLI</span><span class="nv"> </span><span class="s">tool</span><span class="nv"> </span><span class="s">installed"</span>
<span class="na">related_endpoints</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="s2">"</span><span class="s">/api/v2/deployments"</span>
  <span class="pi">-</span> <span class="s2">"</span><span class="s">/api/v2/apps"</span>
<span class="nn">---</span>
</code></pre></div></div>

<p>This frontmatter enables AI systems (and your own search) to:</p>
<ul>
  <li>Match content to user skill level</li>
  <li>Understand context and relationships</li>
  <li>Provide accurate time estimates</li>
  <li>Suggest prerequisite reading</li>
</ul>

<h3 id="3-show-complete-realistic-examples">3. Show complete, realistic examples</h3>

<p>Replace minimal examples with production-ready code that demonstrates real-world usage:</p>

<p><strong>Before:</strong></p>
<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl <span class="nt">-X</span> GET /api/users
</code></pre></div></div>

<p><strong>After:</strong></p>
<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Get paginated user list with error handling</span>
curl <span class="nt">-X</span> GET <span class="s2">"https://api.example.com/v2/users?page=1&amp;limit=10"</span> <span class="se">\</span>
  <span class="nt">-H</span> <span class="s2">"Authorization: Bearer </span><span class="nv">$TOKEN</span><span class="s2">"</span> <span class="se">\</span>
  <span class="nt">-H</span> <span class="s2">"Accept: application/json"</span> <span class="se">\</span>
  <span class="nt">-w</span> <span class="s2">"HTTP Status: %{http_code}</span><span class="se">\n</span><span class="s2">"</span> <span class="se">\</span>
  <span class="nt">--fail-with-body</span>

<span class="c"># Example successful response (200)</span>
<span class="o">{</span>
  <span class="s2">"users"</span>: <span class="o">[</span>...],
  <span class="s2">"pagination"</span>: <span class="o">{</span>
    <span class="s2">"page"</span>: 1,
    <span class="s2">"limit"</span>: 10,
    <span class="s2">"total"</span>: 150,
    <span class="s2">"has_next"</span>: <span class="nb">true</span>
  <span class="o">}</span>
<span class="o">}</span>

<span class="c"># Example error response (401)</span>
<span class="o">{</span>
  <span class="s2">"error"</span>: <span class="s2">"invalid_token"</span>,
  <span class="s2">"message"</span>: <span class="s2">"API key is expired or invalid"</span>
<span class="o">}</span>
</code></pre></div></div>

<h3 id="4-optimize-repository-structure-for-ingestion">4. Optimize repository structure for ingestion</h3>

<p>Tools like <a href="https://gitingest.com/">gitinjest</a> can convert entire repositories into text digests that AI systems can process. If your docs live alongside code, proper repository structure becomes crucial.</p>

<p><strong>Essential practices:</strong></p>
<ul>
  <li><strong>Clean README.md</strong>: Often the first file ingested, make it comprehensive and current</li>
  <li><strong>Logical folder organization</strong>: Use clear hierarchies (<code class="language-plaintext highlighter-rouge">/docs</code>, <code class="language-plaintext highlighter-rouge">/api</code>, <code class="language-plaintext highlighter-rouge">/examples</code>, <code class="language-plaintext highlighter-rouge">/tutorials</code>)</li>
  <li><strong>Include machine-readable specs</strong>: OpenAPI definitions, GraphQL schemas, Postman collections</li>
  <li><strong>Consistent naming conventions</strong>: Make files discoverable and their purpose obvious</li>
</ul>

<p><strong>Example structure:</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>your-repo/
├── README.md                 # Overview, quick start
├── docs/
│   ├── api/                 # API reference
│   ├── tutorials/           # Step-by-step guides
│   └── examples/            # Working code samples
├── openapi.yaml             # Machine-readable API spec
└── .llmsignore             # Files to exclude from AI ingestion
</code></pre></div></div>

<h2 id="advanced-techniques-inline-instructions-and-apis">Advanced techniques: Inline instructions and APIs</h2>

<h3 id="page-level-ai-guidance">Page-level AI guidance</h3>

<p>Vercel recently <a href="https://vercel.com/blog/a-proposal-for-inline-llm-instructions-in-html">proposed</a> embedding page-specific instructions directly in HTML using <code class="language-plaintext highlighter-rouge">&lt;script type="text/llms.txt"&gt;</code> tags. Browsers ignore these, but AI systems can read them.</p>

<p>This approach handles edge cases where page-level context matters:</p>

<div class="language-html highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nt">&lt;head&gt;</span>
  <span class="nt">&lt;script </span><span class="na">type=</span><span class="s">"text/llms.txt"</span><span class="nt">&gt;</span>
<span class="nx">This</span> <span class="nx">is</span> <span class="nx">a</span> <span class="nx">preview</span> <span class="nx">environment</span> <span class="nx">showing</span> <span class="nx">unreleased</span> <span class="nx">features</span><span class="p">.</span>
<span class="nx">For</span> <span class="nx">production</span> <span class="nx">guidance</span><span class="p">,</span> <span class="nx">direct</span> <span class="nx">users</span> <span class="nx">to</span> <span class="nx">https</span><span class="p">:</span><span class="c1">//docs.example.com/stable/</span>
<span class="nx">Authentication</span> <span class="nx">bypass</span> <span class="nx">available</span> <span class="nx">at</span> <span class="o">/</span><span class="nx">auth</span><span class="o">/</span><span class="nx">dev</span><span class="o">-</span><span class="nx">bypass</span> <span class="k">for</span> <span class="nx">testing</span><span class="p">.</span>
  <span class="nt">&lt;/script&gt;</span>
<span class="nt">&lt;/head&gt;</span>
</code></pre></div></div>

<p><strong>Use cases:</strong></p>
<ul>
  <li>Preview/staging environments</li>
  <li>Authentication-required pages</li>
  <li>Temporary or context-specific content</li>
  <li>A/B testing scenarios</li>
</ul>

<h3 id="programmatic-llmstxt-management">Programmatic llms.txt management</h3>

<p>Vercel also provides a <a href="https://vercel.com/docs/rest-api/reference/llms.txt">REST API for llms.txt management</a>, enabling dynamic rule updates:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Get current llms.txt rules</span>
curl <span class="nt">-X</span> GET <span class="s2">"https://api.vercel.com/llms.txt"</span> <span class="se">\</span>
  <span class="nt">-H</span> <span class="s2">"Authorization: Bearer </span><span class="nv">$VERCEL_TOKEN</span><span class="s2">"</span> <span class="se">\</span>
  <span class="nt">-H</span> <span class="s2">"Accept: text/plain"</span>

<span class="c"># Update rules programmatically</span>
curl <span class="nt">-X</span> POST <span class="s2">"https://api.vercel.com/llms.txt"</span> <span class="se">\</span>
  <span class="nt">-H</span> <span class="s2">"Authorization: Bearer </span><span class="nv">$VERCEL_TOKEN</span><span class="s2">"</span> <span class="se">\</span>
  <span class="nt">-H</span> <span class="s2">"Content-Type: text/plain"</span> <span class="se">\</span>
  <span class="nt">-d</span> <span class="s2">"User-Agent: *
Allow: /docs/v3/
Disallow: /docs/v2/"</span>
</code></pre></div></div>

<p><strong>Benefits:</strong></p>
<ul>
  <li>Automate rule updates when releasing new API versions</li>
  <li>Sync crawling rules with deployment pipelines</li>
  <li>Handle complex routing scenarios programmatically</li>
</ul>

<p><strong>Trade-offs:</strong></p>
<ul>
  <li>Adds complexity compared to static files</li>
  <li>Requires authentication and API management</li>
  <li>Potential consistency issues across different pages</li>
</ul>

<h2 id="monitoring-and-validation">Monitoring and validation</h2>

<h3 id="testing-your-llmstxt">Testing your llms.txt</h3>

<p><strong>Syntax validation:</strong></p>
<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Use online validators or build simple checks</span>
curl <span class="nt">-s</span> https://yourdocs.com/llms.txt | <span class="nb">head</span> <span class="nt">-20</span>
</code></pre></div></div>

<p><strong>Monitor compliance:</strong></p>
<ul>
  <li>Check server logs for crawl patterns</li>
  <li>Use tools like Google Search Console (adapted for AI crawlers)</li>
  <li>Set up alerts for unexpected crawling of restricted paths</li>
</ul>

<h3 id="common-mistakes-to-avoid">Common mistakes to avoid</h3>

<p><strong>File placement errors:</strong></p>
<ul>
  <li>❌ <code class="language-plaintext highlighter-rouge">yourdocs.com/docs/llms.txt</code></li>
  <li>✅ <code class="language-plaintext highlighter-rouge">yourdocs.com/llms.txt</code></li>
</ul>

<p><strong>Syntax issues:</strong></p>
<pre><code class="language-txt"># Wrong - missing trailing slash for directories
Disallow: /internal

# Right - include trailing slash
Disallow: /internal/
</code></pre>

<p><strong>Overly restrictive rules:</strong></p>
<pre><code class="language-txt"># This blocks everything - probably not what you want
User-Agent: *
Disallow: /
</code></pre>

<h2 id="handling-edge-cases">Handling edge cases</h2>

<h3 id="multi-language-documentation">Multi-language documentation</h3>
<pre><code class="language-txt"># Language-specific rules
User-Agent: *
Allow: /en/docs/
Allow: /es/docs/
Allow: /fr/docs/
Disallow: /en/docs/legacy/
Disallow: /*/internal/
</code></pre>

<h3 id="graphql-apis">GraphQL APIs</h3>
<pre><code class="language-txt"># Include schema definitions
Allow: /graphql/schema
Allow: /graphql/docs/
Disallow: /graphql/playground/
</code></pre>

<h3 id="authentication-protected-content">Authentication-protected content</h3>
<pre><code class="language-txt"># Clearly mark authenticated sections
Disallow: /dashboard/
Disallow: /admin/
# But allow public auth docs
Allow: /docs/authentication/
</code></pre>

<h2 id="seo-and-robotstxt-interaction">SEO and robots.txt interaction</h2>

<p>Your <code class="language-plaintext highlighter-rouge">llms.txt</code> should complement, not conflict with, your existing <code class="language-plaintext highlighter-rouge">robots.txt</code>:</p>

<p><strong>robots.txt</strong> (for search engines):</p>
<pre><code class="language-txt">User-agent: *
Disallow: /admin/
Disallow: /internal/
Sitemap: https://docs.example.com/sitemap.xml
</code></pre>

<p><strong>llms.txt</strong> (for AI crawlers):</p>
<pre><code class="language-txt">User-Agent: *
Disallow: /admin/
Disallow: /internal/
Disallow: /docs/v1/  # Additional AI-specific restrictions
Allow: /docs/v2/
Content-Type: technical-documentation
</code></pre>

<p>Most AI crawlers respect both files, so maintain consistency where possible.</p>

<h2 id="real-world-examples">Real-world examples</h2>

<p><strong>API-first company (Stripe-style):</strong></p>
<pre><code class="language-txt">User-Agent: *
Allow: /docs/api/
Allow: /docs/guides/
Allow: /docs/webhooks/
Disallow: /docs/legacy/
Disallow: /docs/internal/
Content-Type: technical-documentation
Audience: developers
License: proprietary
Attribution: https://docs.stripe.com
</code></pre>

<p><strong>Open source project:</strong></p>
<pre><code class="language-txt">User-Agent: *
Allow: /docs/
Allow: /api/
Allow: /examples/
Disallow: /docs/drafts/
Content-Type: technical-documentation
License: MIT
Repository: https://github.com/org/project
</code></pre>

<p><strong>Enterprise platform:</strong></p>
<pre><code class="language-txt">User-Agent: *
Allow: /docs/public/
Allow: /api/reference/
Disallow: /docs/enterprise/  # Gated content
Disallow: /docs/beta/
Content-Type: technical-documentation
Audience: developers, system-administrators
</code></pre>

<h2 id="implementation-checklist">Implementation checklist</h2>

<p><strong>Phase 1: Basic setup</strong></p>
<ul>
  <li>✅ Create <code class="language-plaintext highlighter-rouge">llms.txt</code> at your docs domain root</li>
  <li>✅ Disallow deprecated API versions and internal paths</li>
  <li>✅ Allow current documentation and API references</li>
  <li>✅ Add basic metadata (Content-Type, Attribution, License)</li>
  <li>✅ Test file accessibility and syntax</li>
</ul>

<p><strong>Phase 2: Content optimization</strong></p>
<ul>
  <li>✅ Pair all UI-based instructions with equivalent API calls</li>
  <li>✅ Add structured frontmatter to all tutorial and reference pages</li>
  <li>✅ Include realistic, complete code examples with error handling</li>
  <li>✅ Organize repository structure for ingestion tools</li>
</ul>

<p><strong>Phase 3: Advanced features</strong></p>
<ul>
  <li>✅ Implement page-level inline instructions where needed</li>
  <li>✅ Set up monitoring for crawl patterns and compliance</li>
  <li>✅ Create automation for updating rules during releases</li>
  <li>✅ Establish review process for AI-specific content changes</li>
</ul>

<h2 id="looking-ahead">Looking ahead</h2>

<p>The shift toward AI-assisted development is accelerating. Documentation that works well with AI systems will become a competitive advantage, while docs that ignore this trend will become increasingly irrelevant.</p>

<p>Standards like <code class="language-plaintext highlighter-rouge">llms.txt</code> are still evolving. Not all crawlers respect these rules yet, and new patterns for AI-friendly content are emerging rapidly. Stay informed by following:</p>

<ul>
  <li>The <a href="https://llmstxt.org/">llms.txt specification</a> as it develops</li>
  <li>AI company announcements about crawler behavior</li>
  <li>Developer community discussions about documentation best practices</li>
</ul>

<p>Your documentation strategy should anticipate a world where most developer interactions with your content happen through AI intermediaries. By implementing these practices now, you ensure those interactions are accurate, helpful, and aligned with your current product reality.</p>

<p>Your documentation strategy should anticipate a world where most developer interactions with your content happen through AI intermediaries. By implementing these practices now, you ensure those interactions are accurate, helpful, and aligned with your current product reality.</p>

<p>In the next post, we’ll go deeper: how to <strong>structure and publish AI-ready docs</strong>, so when a developer asks an assistant for help, the answer isn’t just “close.” It’s exactly what your docs say.</p>

<p>For deeper insights into this transformation, watch Andrej Karpathy’s excellent <a href="https://www.youtube.com/watch?v=LCEmiRjPEtQ&amp;t=2019s">talk on building docs for the AI era</a>.</p>]]></content><author><name>Dewan Ahmed</name></author><category term="documentation" /><category term="ai" /><category term="devrel" /><summary type="html"><![CDATA[Your docs are training AI models right now. Here’s how to take control.]]></summary></entry><entry><title type="html">The Principal Developer Advocate Paradox: Scaling Impact Without Burnout</title><link href="https://www.dewanahmed.com/being-principal-da/" rel="alternate" type="text/html" title="The Principal Developer Advocate Paradox: Scaling Impact Without Burnout" /><published>2025-03-13T01:00:00-03:00</published><updated>2025-03-13T01:00:00-03:00</updated><id>https://www.dewanahmed.com/being-principal-da</id><content type="html" xml:base="https://www.dewanahmed.com/being-principal-da/"><![CDATA[<p>As a Principal Developer Advocate, you don’t own the roadmap, control the pipeline, set budgets, or dictate campaigns—yet your work influences all of them. Your impact isn’t measured by code written but by friction removed, momentum created, and voices amplified.</p>

<p>The challenge? The more effective you are, the more demand you generate. You risk becoming a bottleneck, pulled into every meeting, every decision, every request. But true success in this role isn’t about being everywhere—it’s about creating <strong>force multipliers</strong>.</p>

<p>Let’s break down the hidden challenges of this role—and how to navigate them without burning out.</p>

<h3 id="paradox-of-belonging">Paradox of Belonging</h3>

<p>You are connected to every team—engineering, product, marketing, community—but you don’t <em>belong</em> to any single one. The role can be surprisingly isolating; you’re expected to bridge gaps, yet you often lack a dedicated home base. Finding circles of trust—peer advocates, engineers who value your input, and mentors—becomes essential to navigating this unique position.</p>

<h3 id="freedom-responsibility-paradox"><strong>Freedom-Responsibility Paradox</strong></h3>
<p>You have significant autonomy in what you choose to work on, but there’s an implicit expectation that your efforts drive measurable impact. Are you truly solving the right problems, or just doing what seems urgent? The solve is to create an <strong>impact framework</strong>—a structured way to assess whether your advocacy, content, and engagement are making a difference. Freedom in this role isn’t about working on what excites you; it’s about owning the mission of amplifying developer success in the highest-leverage way.</p>

<h3 id="bandwidth-challenges-from-social-resource-to-force-multiplier"><strong>Bandwidth Challenges: From Social Resource to Force Multiplier</strong></h3>
<p>It’s easy to become the “go-to person”—the one in every meeting, the voice in every strategy discussion, the person responding to every community question. This leads to burnout, endless context switching, and a diluted ability to create <em>scalable</em> impact. The trick is to shift from being a <strong>reactive resource</strong> to a <strong>strategic force multiplier</strong>:</p>

<ul>
  <li>Writing docs that answer recurring questions so teams can self-serve instead of always coming to you.</li>
  <li>Creating frameworks that enable <em>others</em> to advocate, instead of being the single point of engagement.</li>
  <li>Focusing on content, programs, and initiatives that scale beyond your personal involvement.</li>
</ul>

<h3 id="being-truly-present-even-when-writing-docs"><strong>Being Truly Present (Even When Writing Docs)</strong></h3>
<p>You’re in a meeting, constantly context-switching, your mind racing to the next three tasks, while also drafting a response to a community Slack thread. Developer Advocates juggle multiple domains—public speaking, content creation, product feedback, and internal alignment—which makes it tempting to be <em>everywhere at once</em>. The reality? <em>Presence matters</em>.</p>

<p>✔ When writing content, resist the urge to multitask. Well-written content scales your knowledge far beyond what any single conversation can.</p>

<p>✔ When engaging with teams, be fully present. Not every meeting needs you, but when you’re in the right ones, your focus is your biggest asset.</p>

<p>✔ Protect your deep work time—whether that’s for writing, content creation, or strategic thinking.</p>

<h3 id="the-perfection-trap"><strong>The Perfection Trap</strong></h3>
<p>In engineering, we optimize for correctness. In advocacy, speed and iteration often win. It’s tempting to overanalyze, perfect every talk, refine every article—only to realize that the audience has already moved on. Great Developer Advocacy means accepting that <strong>good content now</strong> is better than <em>perfect</em> content later. It’s about learning in public, iterating fast, and engaging before the moment passes.</p>

<h3 id="authority-paradox"><strong>Authority Paradox</strong></h3>
<p>Contrary to perception, Principal Developer Advocates have <strong>influence, not authority</strong>. You’re expected to drive cross-functional initiatives—impacting engineering roadmaps, developer experience, and community growth—but you don’t control teams, priorities, or budgets. You can’t mandate change. Instead, your success depends on <strong>persuasion, trust, and credibility</strong>. The best Developer Advocates don’t push people to do things; they make others <em>want</em> to take action through clarity, vision, and relentless execution.</p>

<h3 id="the-power-of-saying-no"><strong>The Power of Saying “No”</strong></h3>
<p>With endless requests for your time, saying “yes” to everything means saying “no” to focused, strategic work. The ability to say “no” isn’t about shutting down collaboration—it’s about protecting your ability to make an impact.</p>

<ul>
  <li>If a request isn’t aligned with your mission, redirect it to scalable solutions (docs, videos, workshops).</li>
  <li>Just because you <em>can</em> do something doesn’t mean you <em>should</em>—guard your time for high-leverage work.</li>
  <li>The best Developer Advocates create <strong>systems</strong> that help others succeed <em>without needing them in the loop every time.</em></li>
</ul>

<h3 id="time-to-ship">Time to Ship</h3>

<p>Being a Principal Developer Advocate is a delicate balance between influence and responsibility. You don’t control the tools or the teams, but your impact reverberates through every part of the organization. To thrive in this role, you must understand how to amplify your efforts without being stretched too thin.</p>

<p>This isn’t just about showing up—it’s about showing up where it matters. By focusing on scalable strategies, managing your bandwidth, and creating systems that empower others, you can truly maximize your impact. And when you embrace the power of saying “no,” you protect the precious time that allows you to do your best work, at the highest level.</p>

<p>The role might be paradoxical, but in its heart lies the opportunity to shape the future of developer experience, content creation, and community engagement—<em>without burning out.</em> The key is mastering the art of leverage and focus to become the force multiplier that everyone needs.</p>

<hr />

<p>This blog was inspired by a <a href="https://www.linkedin.com/posts/bhavik-kothari-5768b42a_some-obvious-and-not-so-obvious-challenges-activity-7303872281674465281-s5Mc">LinkedIn post from Bhavik Kothari, Principal Engineer at Amazon</a>.</p>]]></content><author><name>Dewan Ahmed</name></author><category term="community" /><category term="devrel" /><summary type="html"><![CDATA[As a Principal Developer Advocate, you don’t own the roadmap, control the pipeline, set budgets, or dictate campaigns—yet your work influences all of them. Your impact isn’t measured by code written but by friction removed, momentum created, and voices amplified.]]></summary></entry><entry><title type="html">Hosting a (DevOpsDays) Tech Conference</title><link href="https://www.dewanahmed.com/hosting-a-conference/" rel="alternate" type="text/html" title="Hosting a (DevOpsDays) Tech Conference" /><published>2024-09-29T01:00:00-03:00</published><updated>2024-09-29T01:00:00-03:00</updated><id>https://www.dewanahmed.com/hosting-a-conference</id><content type="html" xml:base="https://www.dewanahmed.com/hosting-a-conference/"><![CDATA[<p>In August 2024, we pulled off the first-ever <a href="https://devopsdays.org/events/2024-halifax/welcome/">DevOpsDays Halifax</a>, and wow, what an experience! As one of the organizers, I’ve got a ton of stories, lessons learned, and tips to share. Whether you’re looking to host your own DevOpsDays or just thinking about organizing any tech event, this blog’s for you. From planning to community building, there’s a lot here that can help you on your journey, no matter the type of event you’re aiming to create.</p>

<h2 id="story">Story</h2>

<p>During the pandemic, I relocated from Toronto, Ontario to Moncton, New Brunswick. The move was motivated by the region’s affordable housing, friendly people, and stunning landscapes—Atlantic Canada had everything, except a vibrant tech scene. This void inspired me to start a tech meetup.</p>

<p>Back in Toronto, I had been managing two meetup groups with thousands of members and was a regular speaker at meetups and conferences. When I moved to Atlantic Canada, I knew I wanted to bring that same energy and sense of community to the region. <a href="https://www.linkedin.com/in/diahmed/">I</a> teamed up with <a href="https://www.linkedin.com/in/nahrin-jalal/">Nahrin Jalal</a>, the ideal collaborator for this venture, and together, we launched the Atlantic Canada Tech Meetup on a crisp fall evening, September 29, 2022.</p>

<p><img src="/assets/images/2024/first-meetup.jpeg" alt="First Meetup of Atlantic Canada Tech Meetup" /></p>

<p>Our first event was small and grassroots—I even printed a simple Meetup this way –&gt; sign on an A4 paper and taped it to the door so folks could find us. Despite the modest setup, around 25 people showed up that night, all expressing the same sentiment: they had been searching for a tech event in Halifax but couldn’t find one. This confirmed what we had suspected—there was a real need for a tech community in the region.</p>

<p>Buoyed by this interest, we began hosting bimonthly meetups starting in January 2023. The growth was exponential, and with each event, the community grew stronger. It wasn’t long before Nahrin and I realized that we needed to take this initiative to the next level. We decided it was time to bring a premium developer conference to Atlantic Canada, and that’s how the journey toward organizing DevOpsDays Halifax began.</p>

<h2 id="why-devopsdays">Why DevOpsDays</h2>

<p>When we started thinking about hosting a tech conference, we had two main options: either create something entirely new or bring in an established conference. It’s like the classic software dilemma: do you build your own tool or use something tried and tested? I’ve seen enough DIY disasters in the software world to know that going with an established brand is usually the safer bet.</p>

<p>Now, we wanted a general tech conference that would resonate with the local tech community here in Atlantic Canada. Having spoken at a bunch of DevOpsDays events before, I already knew how much I respected the values and the community around it. DevOpsDays isn’t just about DevOps—it’s about collaboration, continuous improvement, and fostering a space where tech folks can actually connect and learn from each other.</p>

<p>Choosing DevOpsDays was an obvious choice, and it quickly proved to be the right one. With their framework, branding, and organizer support, we were able to tailor the event for our community, bringing global credibility and strong connections to our local tech scene.</p>

<p>The <a href="https://devopsdays.org/organizing">organizing guide</a> is the only resource you need to get started if you’re planning to host a DevOpsDays conference.</p>

<h2 id="forming-the-team">Forming the Team</h2>

<p>Nahrin and I, co-organizers of the Atlantic Canada Tech Meetup, kicked off our search for some motivated folks to help us bring DevOpsDays to life. First up was <a href="https://www.linkedin.com/in/mattjoyyhz/">Matt Joy</a>, a Google Customer Engineer who was actually one of our first speakers at the meetup—so we reached out, and he was all in. Then came <a href="https://www.linkedin.com/in/seifelbayomi/">Seif Elbayomi</a>, a final-year CS student at Dalhousie University. He originally applied as a volunteer, but his application stood out so much that we knew we had to bring him on as an organizer.</p>

<p><img src="/assets/images/2024/organizers.jpg" alt="The Organizing Team" /></p>

<p>We couldn’t have asked for a better team. With a mix of event experience, industry connections, and student reach, our diverse skills and expertise made us a perfect fit to take on the challenge.</p>

<h2 id="operating-with-0-budget">Operating with $0 Budget</h2>

<p>When organizing DevOpsDays Halifax, we had a unique challenge. This wasn’t New York, San Francisco, or Berlin—there were no big tech companies with massive marketing budgets here in Atlantic Canada. In fact, when we started, we had exactly $0.00 in our bank account.</p>

<p>We knew sponsorship would be key to pulling this off, so we reached out to nearly 100 contacts and companies, hoping to find organizations willing to back the event. At first, we had grand visions of hosting it at a convention center or one of the local hotels. However, reality hit hard when we saw the costs. Here’s what we were looking at:</p>

<table>
  <thead>
    <tr>
      <th>Venue</th>
      <th>Minimum Catering Cost</th>
      <th>Total Cost</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Convention Centre</td>
      <td>40000</td>
      <td>52000</td>
    </tr>
    <tr>
      <td>Hotel A</td>
      <td>50000</td>
      <td>55000</td>
    </tr>
    <tr>
      <td>Hotel B</td>
      <td>48000</td>
      <td>55000</td>
    </tr>
  </tbody>
</table>

<p>For a tech conference in Halifax with no funds to start, these prices were far beyond our reach—despite them being a fraction of what venues would charge in larger cities.</p>

<p>Realizing we had to get creative, we began exploring other, more affordable options. That’s when we reached out to Dalhousie University, and they turned out to be a wonderful partner. Not only was their venue rate much more reasonable, but there was also no minimum catering cost, a major win for us. Since venue and food make up the biggest expenses for most events, this gave us the breathing room we desperately needed to move forward.</p>

<p>But we still needed a downpayment to secure the venue. So, we reached out to some of the other DevOpsDays cities for support. DevOpsDays London generously stepped up and offered us the downpayment for the venue—this was in August 2023, a full year before our event. At that point, we didn’t even have a sponsorship prospectus ready, but we knew we needed to lock in the date and venue to take the next steps.</p>

<p>A heartfelt shoutout to <a href="https://www.linkedin.com/in/bob-walker-8ab30b4/">Bob</a> and the <a href="https://www.linkedin.com/company/devopsdays-london">DevOpsDays London</a> team—you embody the spirit of the DevOpsDays community. Without your early support, there’s a good chance this event wouldn’t have happened.</p>

<p>Now, here’s a bit of a humble brag: DevOpsDays Halifax took frugality to new heights when it came to pulling off a tech conference on a shoestring budget. I can’t help but wonder if any other DevOpsDays event managed to happen with less! If so, I’d love to hear that story.</p>

<h2 id="not-for-profit-or-not">Not-for-profit or Not?</h2>

<p>One of the first big decisions we faced as organizers was whether to set up DevOpsDays Halifax as a not-for-profit. Going this route has clear advantages: it opens the door to a variety of public and private funding opportunities that aren’t available to for-profit ventures. As a community-driven event, our goal was never to make a profit—in fact, many of us ended up covering out-of-pocket expenses to make it happen. So, aligning with not-for-profit principles seemed like a natural fit.</p>

<p>However, becoming a not-for-profit comes with its own set of challenges. There’s the overhead of registering the organization, setting bylaws, filing annual documents with Corporations Canada, and ensuring compliance with specific regulations. As first-time organizers already juggling countless tasks, the additional hassle and administrative burden outweighed the potential benefits at that moment.</p>

<p>We also discovered that many companies with not-for-profit sponsorship programs have long lead times. Some require applications to be submitted six months or more in advance—far too early for us, given where we were in the planning process. This made it clear that while not-for-profit status might help with future events, it wasn’t going to provide immediate sponsorship opportunities for our first year of DevOpsDays Halifax.</p>

<p>In the end, we decided to move forward without formal not-for-profit status. Our focus was on getting the event off the ground, even if it meant leaning more on personal resources and sponsorship hustle than on the perks that could come with official registration.</p>

<h2 id="venue">Venue</h2>

<p>We were fortunate to partner with Dalhousie University for the venue, which turned out to be an ideal fit for DevOpsDays Halifax. The Scotiabank Auditorium, located in the heart of downtown Halifax, could comfortably seat 215 attendees, making it the perfect size for our first conference. In addition to the auditorium, we also booked two extra rooms—one designated as a space for organizers and volunteers to manage behind-the-scenes logistics, and another as a speaker lounge where presenters could prepare for their sessions.</p>

<p>Dalhousie’s central location was a big win for attendees. It’s within walking distance of plenty of hotels and restaurants, making it easy for out-of-town guests to settle in and enjoy the event. Plus, being only a 30-minute drive from Halifax Stanfield International Airport, it was convenient for speakers and attendees flying in from outside the city.</p>

<p>One of the best parts about choosing Dalhousie was the built-in A/V capabilities that came with the auditorium. They provided essential tech, but we supplemented it with extra equipment—renting additional microphones for the emcee and ensuring we had everything needed to keep the event running smoothly. We also rented tables and chairs for the registration desk and sponsor booths, which helped create a professional setup for attendees to interact with our sponsors and check in without any fuss.</p>

<p>Dalhousie University not only gave us a beautiful, accessible venue, but it also helped us stay within budget, providing everything we needed to pull off a successful event.</p>

<h2 id="catering">Catering</h2>

<p>Catering turned out to be one of the biggest line items in our budget, taking up about 60% of the conference’s overall costs. We wanted to make sure attendees were well-fed throughout the day, so we offered a full lineup of meals: breakfast, morning snacks, lunch, afternoon snacks, and (what we thought would be) unlimited coffee.</p>

<p>Given our razor-thin budget, we had to make some tough decisions. While we would have loved to offer a healthier breakfast spread, we opted for more economical choices like pastries, muffins, fruits, and other items that fit within our means. Most of the snacks were bulk-bought from Costco to save costs. For lunch, we kept it simple but satisfying: on the first day, we served wraps and salad, and on the second day, we switched it up with veggie platters and pizza.
One of the key challenges we faced with catering was around the coffee—an essential at any tech conference.</p>

<p>Dalhousie Catering didn’t offer an unlimited coffee option, so we budgeted enough for about two cups per attendee per session. Unfortunately, things didn’t go quite as smoothly as planned. The coffee ran out much faster than anticipated, it wasn’t always hot, and there were no decaf options, which was a disappointment. While the coffee situation was less than ideal, we did our best to keep things moving.</p>

<p>Despite the budget constraints, we made sure to accommodate everyone’s dietary restrictions. We collected preferences during the registration process and worked closely with the caterers to ensure no one was left out. Every attendee was well-fed, and we regularly reminded everyone to stay hydrated throughout the day.</p>

<p>We also took extra care of our speakers by stocking their room with snacks and drinks, ensuring they had a comfortable space to relax between sessions.
In the end, while the catering wasn’t perfect, we did the best we could with the resources we had and ensured that everyone was looked after.</p>

<h2 id="volunteers">Volunteers</h2>

<p>Our volunteers were the backbone of DevOpsDays Halifax. From the start, we knew that with a limited budget, volunteers would play a crucial role in making the event run smoothly. We began by identifying the different roles we needed to fill: registration desk, photography and videography (since we couldn’t afford professional photographers), A/V support, social media, setup and teardown, general help, and a cloud workshop volunteer.</p>

<p>To recruit the right people, we opened up a volunteer application form and promoted it through social media and Dalhousie University’s student networks. The response was overwhelming—we received 60 applications for just 10 volunteer positions! It was tough to choose, but we ultimately selected a fantastic team of dedicated individuals.</p>

<p>In the week leading up to the conference, we organized a volunteer training session to make sure everyone was prepared and knew their responsibilities. Communication was key, so we set up a WhatsApp group where we could easily coordinate and share real-time updates throughout the event.</p>

<p><img src="/assets/images/2024/team-devopsdays-halifax.jpg" alt="Volunteers" /></p>

<p>Our volunteers were nothing short of amazing. Their energy, commitment, and attention to detail made the event possible. Whether it was greeting attendees, capturing memorable moments, or helping with technical setups, they stepped up and delivered. We genuinely cannot thank them enough.</p>

<h2 id="website-cfp-and-ticket-sales">Website, CfP, and Ticket Sales</h2>

<p>One of the significant advantages of organizing a DevOpsDays event instead of a generic tech conference is the extensive support provided by the DevOpsDays community. They offer a framework and hosting for your event website, which we built using a Hugo template. While we had to submit pull requests to customize and launch our site, the support made it much easier to establish our online presence. You can check out our site here: <a href="https://devopsdays.org/halifax">DevOpsDays Halifax</a>.</p>

<p>For the Call for Proposals (CfP), DevOpsDays provided us with a hosted instance of <a href="https://pretalx.com/">Pretalx</a>, which streamlined the process and saved us from paying for a service like Sessionize or similar platforms. Setting it up was straightforward, allowing us to focus on curating quality content for our attendees.</p>

<p>When it came to ticket sales, we benefited once again from the DevOpsDays resources. They offered a hosted instance of <a href="https://pretix.eu/">Pretix</a>, enabling us to manage ticket sales without the fees associated with platforms like Eventbrite. This was especially important for us, as we aimed to keep costs low while providing access to a diverse audience.</p>

<p>Additionally, we had access to Hosted <a href="https://sendy.co/">Sendy</a> for email marketing and Hosted <a href="https://www.vaultproject.io/">Vault</a> for secure password management, which are valuable tools for event organizers. While we didn’t utilize these services this year, we look forward to incorporating them into our planning for next year’s event.</p>

<p>To support inclusivity, we offered deep discounts for students and individuals from underrepresented groups in tech. We believe that fostering a diverse community is essential for the growth and sustainability of our tech ecosystem.</p>

<h2 id="cfp-review">CfP Review</h2>

<p>To ensure we had a diverse and well-rounded review process, we invited a professor from Dalhousie University to join our CfP (Call for Papers) review committee. This addition helped us reach quorum and brought in valuable external insights.</p>

<p>Using Pretalx made the entire process of scoring and reviewing talks much more manageable. The platform allowed us to conduct the initial review asynchronously, but we also blocked off a few two-hour calls to finalize the selections. The built-in email templates for various stages—such as talk acceptance, confirmation, and rejection—were particularly helpful in streamlining communication.</p>

<p>We followed a phased approach to sending out acceptance emails:</p>
<ul>
  <li>Keynote speakers were booked three months or earlier before the event.</li>
  <li>First-round accepted speakers were notified two months before the conference.</li>
  <li>For those who didn’t confirm their participation in the first round, we reached out to a waiting list of speakers six weeks before the event in a second phase.</li>
</ul>

<h2 id="finally-sponsors-">Finally… Sponsors 😅</h2>

<p>Securing sponsors was one of the most nerve-wracking parts of organizing DevOpsDays Halifax. We knew that sponsorships were essential to cover event costs and make the conference a reality, but the process took time and a lot of hustle.</p>

<p>Our first major breakthrough came when we started a conversation with <strong>Digital Nova Scotia</strong>, the industry association for Nova Scotia’s $3.6 billion ICT and digital technologies sector. They quickly saw the value in supporting the event and came on board as a gold sponsor. Welcoming Digital Nova Scotia was a huge milestone for us, as it meant we had the backing of one of the most influential tech organizations in the province.</p>

<p>Just a few weeks before the conference, <strong>SUSE</strong>, a multinational company known for its enterprise-grade Open Source products based on Linux technologies, joined as another gold sponsor. Their support not only bolstered our budget but also brought a level of prestige to the event, showcasing the international interest in our local DevOps community.</p>

<p>We were also thrilled to have <strong>MOBIA</strong>, a local tech company that helps businesses achieve their potential through digital transformation and thought leadership, join as a silver sponsor. Their commitment to the Halifax tech scene and their support of community-driven initiatives like ours made them a perfect fit for the event.</p>

<p>With these sponsors on board, the dream of DevOpsDays Halifax was finally becoming a reality. Their support provided the financial backbone we needed to pull off the conference, and we couldn’t be more grateful for their belief in our vision.</p>

<h2 id="event-logistics">Event Logistics</h2>

<p>Organizing a successful conference requires careful attention to logistics, especially on the day(s) of the event. Here are some key things to watch out for, drawn from our own experiences and those of others in the DevOpsDays community:</p>

<ul>
  <li>
    <p><strong>Sound and Video Checks</strong>: Run a sound and video check as early as feasible, and do another one as late as possible. Your AV situation can change as things are set up, so it’s vital to ensure everything is functioning smoothly.</p>
  </li>
  <li>
    <p><strong>Wi-Fi Troubleshooting</strong>: If you encounter Wi-Fi problems, don’t hesitate to ask your local admin or network operations center (NOC) to reset the access point closest to the registration desk. This AP handles most connections, and resetting it can help distribute the load more evenly.</p>
  </li>
  <li>
    <p><strong>Stay Hydrated</strong>: You won’t drink enough water, so keep reminding yourself to stay hydrated throughout the day. Stock up on water and encourage your team to do the same.</p>
  </li>
  <li>
    <p><strong>Emergency Supplies</strong>: Be prepared for the unexpected. If you find yourself missing an item, sending someone to a nearby convenience store can save the day. One organizer shared an experience where they managed to bring in about 100 bottles of water on just 30 minutes’ notice—so don’t underestimate the power of quick solutions!</p>
  </li>
  <li>
    <p><strong>Communication</strong>: Have a plan for how you’ll communicate with other organizers, and test it in advance. Slack has not worked well for us in the past, as messages can easily be overlooked. One organizer recounted a year when they used two-way radios, only to discover that two nearby construction crews were using the same frequency. Check with your venue for their frequencies if you choose this option.</p>
  </li>
  <li>
    <p><strong>Volunteer Coordination</strong>: Create a schedule outlining who is doing what to ensure a fair distribution of tasks. This helps avoid situations where more introverted volunteers are left to manage the registration desk all day.</p>
  </li>
  <li>
    <p><strong>Be Realistic</strong>: Don’t try to be everywhere at once—remember, it’s a marathon, not a sprint. Things will go wrong, and it’s important to give yourselves grace. No one knows how the event was supposed to look in your mind; they only see what’s happening in front of them.</p>
  </li>
  <li>
    <p><strong>Badge Management</strong>: Have blank badges and permanent markers on hand for attendees who lose theirs. If you’re using cardboard badges, ensure you have a way to repair them at the registration desk.</p>
  </li>
  <li>
    <p><strong>Run of Show</strong>: A detailed run of show should cover everything from when food is set out to who is responsible for turning off the last projector. For DevOpsDays Halifax, I initially set out to create a detailed Run of Show, drawing inspiration from <a href="https://docs.google.com/spreadsheets/d/1cJGk7DTlbKP1V7ljshubuI2kf46HXchJna3gdADA71c">the one used at DevOpsDays Austin</a> (courtesy of Laura from DevOpsDays Austin). I spent a few late nights trying to make it as comprehensive as possible. However, as the event unfolded, it became clear we didn’t need that level of detail. Our event wasn’t as large, and we didn’t have multiple rooms or complex logistics like Austin. In the end, a simple schedule with a few personal notes for the Emcees was more than enough.</p>
  </li>
</ul>

<p>This experience taught me an important lesson: while it’s great to take inspiration from other events, no two are the same. Just because something works for one city or conference doesn’t mean it will suit yours. It’s essential to adapt your planning and logistics to fit the unique scale and needs of your event.</p>

<ul>
  <li>
    <p><strong>Speaker Management</strong>: Designate a speaker wrangler who knows all the speakers and can track down anyone who might be missing just before their talk. This role is crucial for keeping the schedule on track.</p>
  </li>
  <li>
    <p><strong>Visibility for Organizers and Volunteers</strong>: Make sure organizers and volunteers are easily identifiable, whether through brightly colored t-shirts or unique hats. This way, attendees can find help when they need it. At DevOpsDays Halifax 2024, we used different colored lanyards for the hosts and volunteers.</p>
  </li>
  <li>
    <p><strong>Code of Conduct (CoC)</strong>: While we hope you never have to address a code of conduct issue, it’s wise to have an action plan in place. Always send two organizers to discuss any inappropriate behavior to ensure there’s a witness to the conversation, preferably with a mix of genders. For reference, here’s the <a href="https://devopsdays.org/events/2024-halifax/conduct">CoC for DevOpsDays Halifax</a>.</p>
  </li>
  <li>
    <p><strong>Build Relationships with Venue Staff</strong>: Being friendly and polite to venue staff can pay off when you have last-minute requests or realize something has been overlooked.</p>
  </li>
  <li>
    <p><strong>MC Preparedness</strong>: Ensure the MC knows how to fill time if needed. Having a few groan-worthy dad jokes on hand can lighten the mood, especially during technical difficulties or when a speaker finishes early. A skilled MC can smooth over any rough edges and keep the event flowing. At DevOpsDays Halifax 2024, we were super lucky to have two of our awesome speakers also wear the hats as Emcees.</p>
  </li>
</ul>

<h2 id="open-spaces-at-devopsdays-halifax">Open Spaces at DevOpsDays Halifax</h2>

<p>At DevOpsDays Halifax, the Open Spaces became a powerful hub for connection and conversation. For those unfamiliar, Open Spaces are self-organized discussions where attendees suggest topics they’re passionate about or want to learn more about. It’s a flexible and dynamic format, encouraging participants to join or leave conversations as they see fit, guided by the “Law of Mobility” — if you’re not getting value or contributing, you’re free to move to another session.</p>

<p>While many at our event were new to the concept, they quickly embraced it. This year, the focus of most discussions was around finding jobs in tech, a reflection of the current market conditions. We had a great mix of hiring managers, seasoned professionals, and student developers sharing advice, strategies, and opportunities for breaking into or advancing in the tech field.</p>

<p>The open, self-organized nature of these sessions allowed everyone to participate, whether seeking guidance or offering it. It truly showcased the collaborative spirit of DevOps, where every voice mattered, and everyone left with something valuable.</p>

<p><img src="/assets/images/2024/open-spaces.jpg" alt="Open Spaces at DevOpsDays Halifax 2024" /></p>

<h2 id="post-conference-todos">Post-Conference TODOs</h2>

<p>Assigning someone to lead post-conference tasks is essential. For DevOpsDays Halifax, our team worked relentlessly leading up to and during the event, but once it was over, we were quickly consumed by our regular jobs. Meanwhile, we still had to publish the slides, sort through 12,000 photos to highlight the best moments, and edit 20 hours of video content. Our student volunteers were back at school, and we were all swamped with other responsibilities. This experience taught me the importance of planning for post-conference tasks well in advance. Including post-event activities in your overall planning ensures nothing falls through the cracks when the event is over.</p>

<h2 id="a-celebration-of-community-and-collaboration">A Celebration of Community and Collaboration</h2>

<p>Organizing DevOpsDays Halifax was both a challenge and a triumph. From the early stages of planning to the final moments of the event, every step was a learning experience. We relied on an amazing team of volunteers, navigated the complexities of sponsorships, and pulled off event logistics that could have easily overwhelmed us. Along the way, we discovered that while inspiration from other events is valuable, each conference has its own unique rhythm and requirements—what works for one may not work for another, and that’s okay.</p>

<p>More importantly, we saw firsthand the power of community. Whether it was the support from local sponsors, the dedication of our volunteers, or the insightful contributions from our speakers, DevOpsDays Halifax became a reality because people came together with passion, energy, and a shared vision. The event wasn’t just about talks or workshops—it was about building connections, sharing knowledge, and fostering a stronger tech community in Atlantic Canada.</p>

<p>Looking back, there were challenges we didn’t anticipate, but we adapted, learned, and grew as organizers and as a team. As we move forward, the lessons we’ve learned will only help us improve and create even better experiences in the future. To anyone thinking about organizing a tech event, my advice is simple: embrace the journey, accept that things won’t always go as planned, and lean on your community—because that’s where the real magic happens.</p>

<p>DevOpsDays Halifax transcended the boundaries of a typical conference; it became a true celebration of collaboration, innovation, and resilience. As we sailed through memorable moments together, we strengthened our bonds and ignited new ideas that will fuel our journey forward. While this year’s event has drawn to a close, we’re already looking ahead to the next chapter—see you at DevOpsDays Halifax 2025!</p>

<p><img src="/assets/images/2024/team-cruise.jpg" alt="Speaker Cruise" /></p>]]></content><author><name>Dewan Ahmed</name></author><category term="community" /><category term="devops" /><summary type="html"><![CDATA[In August 2024, we pulled off the first-ever DevOpsDays Halifax, and wow, what an experience! As one of the organizers, I’ve got a ton of stories, lessons learned, and tips to share. Whether you’re looking to host your own DevOpsDays or just thinking about organizing any tech event, this blog’s for you. From planning to community building, there’s a lot here that can help you on your journey, no matter the type of event you’re aiming to create.]]></summary></entry><entry><title type="html">Connecting the dots: Let’s get ship done!</title><link href="https://www.dewanahmed.com/joining-harness/" rel="alternate" type="text/html" title="Connecting the dots: Let’s get ship done!" /><published>2023-09-25T01:00:00-03:00</published><updated>2023-09-25T01:00:00-03:00</updated><id>https://www.dewanahmed.com/joining-harness</id><content type="html" xml:base="https://www.dewanahmed.com/joining-harness/"><![CDATA[<p>Today I’m joining Harness as a Principal Developer Advocate. Harness is a complete software delivery platform whose mission is to enable the 30M+ software developers in the world to deliver code to their users reliably, efficiently, securely and quickly. Joining Harness is a significant milestone in my professional career and I’m excited to tell you a bit more in this blog.</p>

<h2 id="from-electrical-engineering-to-tech">From Electrical Engineering to Tech</h2>

<p>Back in 2011, I was a fresh face in Canada, ready with an Electrical Engineering degree, a bunch of research papers under my belt, and some work experience. Little did I know, though, that engineering is a regulated profession in Canada and comes with its fair share of red tape. For many international engineering grads like me, joining the workforce meant going back to school and redoing my entire engineering degree. This was a world away from the “tech” scene, where what you know matters more than any piece of paper.</p>

<p>As an older student trying to make ends meet, I had to juggle three part-time jobs. The only free time I could squeeze out of my crazy schedule was for exams and volunteering at the IEEE student club. Fast forward to 2014, and I stumbled upon an opportunity that felt like a golden ticket. A friend from the Ryerson IEEE student club posted about IBM’s search for Java-savvy interns. While Electrical Engineering programs didn’t offer as many programming courses as Computer Science, I excelled in my Java course.</p>

<p>The school internship was exclusively available for 3rd-year students. So, how did a second-year Electrical Engineering student like me even consider applying to IBM? I was driven by a hunger for success, and I knew I had to create my own path rather than following the conventional route. As the saying goes, “You miss 100% of the shots you don’t take,” and I was determined not to miss this opportunity. I got the job at IBM and this marked the beginning of an amazing eight-year adventure with IBM + Red Hat.</p>

<h2 id="quest-to-find-my-superpowers">Quest to find my superpower(s)</h2>

<p>In 2017, I was a competent developer, but I knew that coding wasn’t my superpower. I enjoyed the part which turned code into software. As I explored more, I started learning docker, Kubernetes, OpenShift, and various CI/CD tools. One key difference-maker was that I chose to learn in public. Over the next three years, I established myself as the go-to DevOps expert on the team. I had many senior IBMers send “thank you” notes for my talks and tutorials that helped them with customer projects. I found one of my superpowers.</p>

<p><img src="/assets/images/2023/ibm-kudos.png" alt="IBM Kudos" /></p>

<p>IBM also had a Toastmasters club, and I eagerly joined to network with fellow IBMers and improve my public speaking skills. While most of my peers dreaded public speaking and writing documentation, I enjoyed doing both and these seemed to come naturally to me. I was about to realize my second superpower.</p>

<p>Around that time, an internal role as a developer advocate opened up at IBM. Reading the job description, I realized that I was doing all those things (and more) in my spare time. I was organizing meetups, writing content, delivering (internal) talks. I just didn’t know that the term “developer advocate” existed and I could get paid for doing the things I love.</p>

<p>“‘Passion’ may be an overused word, but I’ll use it here: the work I do as a developer advocate isn’t just a job; it’s my passion. Working in this role has propelled my career to new heights that wouldn’t have been possible had I remained in Electrical Engineering. In case you’re encountering the term for the first time, I’ve shared my perspective on what it means to be <a href="https://www.dewanahmed.com/why-paying-devrel/#who-is-a-developer-advocate">a developer advocate</a>.</p>

<h2 id="connecting-the-dots">Connecting the dots</h2>

<p>Steve Jobs once said, “You cannot connect the dots looking forward. You can only connect the dots looking backward.” I have a corollary to add here. The dots in your career align better when you have the power of connections. You might ask, “Does luck play a factor here?” Most certainly. We are all familiar with the saying, “The more I practice, the luckier I get.” While grit and hard work are paramount for success, a strong professional network can open numerous doors for you. What may appear as luck is, in reality, the power of connections.</p>

<p>Joining IEEE or Toastmasters clubs wasn’t a part of my job description, but I pursued them anyway in the hope of building new connections. Meaningful connections surpass the value of hard work alone. While you can improve your skills at work, a strong connection can unlock opportunities that hard work alone cannot provide. Over the past 12 years, I’ve actively cultivated meaningful professional relationships, ensuring that when I look back and try to connect the dots, they align more seamlessly.</p>

<h2 id="recognition--stability--title--pay">Recognition &gt; Stability &gt; Title &gt; Pay</h2>

<p>This is my own formula to assess work happiness.</p>

<p>Pay is important to me because I have a mortgage and bills to pay. The grocery store doesn’t accept company values or the vision in exchange for bread. However, I believe that happiness comes from being content, not from chasing more money. Once a certain pay threshold is met, I find happiness in working for a company with the right title, stability, and recognition.</p>

<p>The statement ‘Titles don’t matter’ reflects a position of privilege. As an immigrant who once worked as a retail clerk at Staples for $10.25/hour, I care a lot about my title. My title signifies how a company values my worth and directly affects my career progression. A wrong title can limit my career possibilities and hinder my earning potential. That’s why I prioritize titles over pay.</p>

<p>Imagine receiving an offer to join a company with double the pay and a higher title. However, the company closes its doors in a few months, or there’s a sudden change in priorities, leading to the entire DevRel team being let go. What good is the pay increase or title in such a situation? I prefer career stability over a title and pay bump. Coming to work with the constant fear of the next sudden all-hands meeting, where you might be let go, is a terrible feeling, and it hampers one’s ability to perform at their best. This is why I value stability over title and pay.</p>

<p><img src="/assets/images/2023/mithun-kudos.png" alt="Red Hat Kudos" /></p>

<p>Mithun was my second-line manager at Red Hat. Both my then-manager, Jay Dobies, and Mithun made me feel celebrated at work. There’s a saying that goes, ‘Work where you’re celebrated, not tolerated.’ You may have heard of test-driven development, but recognition-driven development is the best kind. Recognition &gt; Stability &gt; Title &gt; Pay because being recognized by management gives me the confidence and mental boost to engage in more meaningful work. The opposite is also true. An important note is by “recognition”, I’m referring to public praise and appreciation, not necessarily to promotions or pay raises.</p>

<h2 id="why-harness">Why Harness</h2>

<p>I set a very high bar when assessing my next employer. While most candidates focus on preparing for interviews, they often forget that interviews are a two-way street. I interviewed Harness, as a company, the same way they interviewed me. I may be biased, but I can confidently say that Harness passed my assessment with flying colors. Here are the seven steps in my interview process for evaluating Harness:</p>

<h3 id="1-the-offer">1. The offer:</h3>

<p>This is the most basic test. Do they satisfy my minimum required title/pay/PTO requirement? I received a strong offer from Harness so this part was a ✅.</p>

<h3 id="2-product-candidate-fit">2. Product-Candidate-Fit:</h3>

<p>If you were to ask my former colleagues what I’m known for, you’d likely hear keywords like DevOps, CI/CD, GitOps, Tekton, Argo CD, and Kubernetes. I can create content at both 101 and 201 levels for most technologies, but DevOps and CI/CD are my forte. I can delve deep into these topics, so when I was considering my next employer, I sought a company whose main focus was on technologies I excel at.</p>

<h3 id="3-excitement-factor">3. Excitement Factor:</h3>

<p>Developer advocacy is a unique role that requires genuine belief in the product to effectively evangelize it. That’s why I tried and tested the Harness platform to see if it genuinely excited me. From robust documentation to user-friendliness and enterprise readiness, I could envision myself helping developers tackle software delivery challenges using the Harness platform. If you haven’t tried Harness yet, I encourage you to <a href="https://app.harness.io/auth/#/signup/?module=cd&amp;utm_source=dewan&amp;utm_medium=dewan-ahmed-blog&amp;utm_campaign=cd-devrel&amp;utm_content=joining-harness">sign up for free</a> and see for yourself.</p>

<h3 id="4-the-interview-process">4. The interview process:</h3>

<p>An interview process can provide significant insights into a company. I actively maintain professional connections with recruiters. When I started looking for the next adventure, I reached out to my recruiter friend at Harness. Thanks to the connection and trust we had established in the past, the interview process felt less formal and more authentic. It involved a transparent and efficient assessment of my skills and experience (no leetcode interview 😉). Following the interview process, Harness didn’t present a lowball offer, and I didn’t play negotiation games. The process moved swiftly, and within four weeks, both parties had reached a signed agreement.</p>

<h3 id="5-the-brand-assessment-of-the-company">5. The brand assessment of the company:</h3>

<p>When I put on a company t-shirt and speak in public, my personal brand is attached to the company brand. During the interview process, I conducted some research on Harness. From <a href="https://www.crunchbase.com/organization/harness-512d">crunchbase</a> to <a href="https://www.linkedin.com/company/harnessinc/">LinkedIn</a> to <a href="https://www.harness.io/company/press-and-news">Harness in press</a>, I found out that Harness is on a solid growth trajectory and has a strong brand presence.</p>

<h3 id="6-the-founders">6. The founder(s):</h3>

<p>I’ve long been an admirer of <a href="https://www.linkedin.com/in/jyotibansal/">Jyoti Bansal</a>. Jyoti has a tremendous track record of leading high-growth technology companies. Beyond his business acumen, he is very technical (more than 25 US patents). Highly technical founders have always been a key factor in my decision to join a tech startup. Since we’re discussing the interview, here’s one of Jyoti’s posts that I found inspiring:</p>

<p><img src="/assets/images/2023/jyoti-post.png" alt="Jyoti Post" /></p>

<p>To answer this question, I was most proud of the work I did with Terraform at Aiven. I heard from multiple customers that Aiven Terraform Provider and the related docs were one of the main reasons they chose Aiven. I authored Aiven Terraform Cookbook - a bunch of commonly used Terraform manifests to deploy data services. This cookbook was heavily used by Aiven’s solution architects.</p>

<h3 id="7-the-direct-leadership-and-understanding-of-devrel">7. The direct leadership and understanding of DevRel:</h3>

<p>Recently, I wrote about the <a href="https://www.dewanahmed.com/identity-crisis-devrel/">identity crisis in DevRel</a>. From influencer marketing to sales and everything in between, many companies have misunderstood the role of DevRel. I wanted to ensure that my definition of impactful DevRel work aligned with that of Harness’s leadership. To my pleasant surprise, my direct leadership at Harness not only shared the same understanding of DevRel and its impact as I did but had also read my blogs on developer relations before the interview.</p>

<h2 id="lets-get-ship-done">Let’s Get Ship Done</h2>

<p>There’s a massive market opportunity for solving enterprise software delivery challenges. Traditional CI/CD within a single network for a monolithic app is rarely the solution. Today’s enterprise customers are building within air-gapped environments, automating secret management, and seeking an intelligent delivery pipeline capable of troubleshooting build and deployment failures, identifying and helping resolve security vulnerabilities in real-time, all with a privacy-first approach.</p>

<p>During last week’s {Unscripted} 2023 conference, Harness <a href="https://www.prnewswire.com/news-releases/harness-introduces-four-new-modules-to-enhance-efficiency-collaboration-and-security-across-the-software-delivery-lifecycle-301934922.html">announced</a> the official release of four new product modules on the platform: Harness Code Repository, Harness Internal Developer Portal, Harness Infrastructure as Code Management, and Harness Software Supply Chain Assurance. With these advancements, it’s an exhilarating time to be part of Harness as we push the boundaries of software delivery and elevate the developer experience. I’m beyond excited to return to my DevOps and CI/CD roots and join Harness to GET SHIP DONE!</p>]]></content><author><name>Dewan Ahmed</name></author><category term="career" /><summary type="html"><![CDATA[Today I’m joining Harness as a Principal Developer Advocate. Harness is a complete software delivery platform whose mission is to enable the 30M+ software developers in the world to deliver code to their users reliably, efficiently, securely and quickly. Joining Harness is a significant milestone in my professional career and I’m excited to tell you a bit more in this blog.]]></summary></entry><entry><title type="html">Going Beyond ‘Do You Know Of Any Open Positions?’</title><link href="https://www.dewanahmed.com/do-you-know-of-any-open-positions/" rel="alternate" type="text/html" title="Going Beyond ‘Do You Know Of Any Open Positions?’" /><published>2023-07-11T21:00:00-03:00</published><updated>2023-07-11T21:00:00-03:00</updated><id>https://www.dewanahmed.com/do-you-know-of-any-open-positions</id><content type="html" xml:base="https://www.dewanahmed.com/do-you-know-of-any-open-positions/"><![CDATA[<blockquote>
  <p>I’m looking for a job in $SomeField. Do you know of any open positions?</p>
</blockquote>

<p>I’ve spent countless hours over the last 9 years to help folks start a career in tech. However, every time I receive this question, I can’t help but cringe a bit. In this blog, I will discuss why this seemingly innocent generic question is unhelpful for both the person asking and the one being asked. I’ll share some practical strategies for job seekers to boost their chances of success by making specific requests and engaging meaningfully with their connections.</p>

<h2 id="the-limitations-of-asking-for-open-positions">The Limitations of Asking for Open Positions</h2>

<p>When job seekers reach out to their connections on LinkedIn asking if they know of any open positions in a specific technology or field (often the very first message they send as soon as connected), they overlook several key factors. Firstly, job openings are often posted publicly, and candidates can readily search for them on their own. Secondly, expecting a contact to remember and keep track of multiple job seekers in various fields is neither practical nor scalable. However, there is a third reason why this approach is ineffective: the lack of personalization. When your initial message to someone on LinkedIn is a generic request for help, it hampers the ability to establish meaningful connections. It is crucial to demonstrate genuine interest in the person you are seeking help from. Have you taken the time to read their blog or explore their work? Have you offered a genuine compliment or acknowledgment of their expertise? Building rapport and showing a genuine interest in the individual increases the likelihood of receiving a positive response and fostering a more meaningful connection.</p>

<h2 id="the-power-of-specific-requests">The Power of Specific Requests</h2>

<p>Instead of making a generic inquiry, job seekers can significantly enhance their chances of receiving relevant assistance by being more specific in their requests. By tailoring their outreach and highlighting their needs, candidates can engage their connections more effectively. For instance, rather than asking about open positions, consider the following alternatives:</p>

<ol>
  <li>
    <p>Requesting a connection for an introduction: If the hiring manager or a decision-maker is a first-degree contact of your connection, it may be beneficial to request an introduction or connection to facilitate your application.</p>
  </li>
  <li>
    <p>Seeking guidance: If you have identified a job opening of interest, ask for insights or advice about the company culture, the team, or any specific information that would help you tailor your application.</p>
  </li>
  <li>
    <p>Resume and LinkedIn review: Requesting a review of your resume or LinkedIn profile is a proactive way to engage your connections. Constructive feedback can significantly improve your chances of standing out in the competitive job market. (Hint: I’ve been offering free resume reviews for the last 9 years and have reviewed over 1000 resumes. <a href="https://www.linkedin.com/in/diahmed/">Connect with me</a> and send a DM for a free resume review.)</p>
  </li>
</ol>

<h2 id="proactive-job-search-strategies">Proactive Job Search Strategies</h2>

<p>I always encourage seeking help for your career, but if you can handle things on your own, there’s no need to burden others with unnecessary requests. For instance, if you send me a resume full of typos, it gives the impression that you didn’t even bother to run a quick grammar/spelling check. Similarly, a simple LinkedIn search will show you all the available jobs. So, before reaching out, try taking a proactive approach to your job search. Here are some strategies to consider:</p>

<ul>
  <li>
    <p>Utilize job search tools: Make use of LinkedIn’s robust job search features to find relevant positions. Narrow down your search by filtering according to location, industry, experience level, and more. Here are some free tools:</p>

    <ul>
      <li>You can use LinkedIn for job search. For many folks, however, reaching out to contacts directly on LinkedIn works better than simply a LinkedIn Easy-Apply. OTOH, <a href="https://news.ycombinator.com/jobs">HN</a> and <a href="https://wellfound.com/jobs">Wellfound (f.k.a. Angel.co)</a> might have better success rate than LinkedIn jobs.</li>
      <li>Google Drive –&gt; New Google Doc –&gt; From template –&gt; Resume will give you a simple resume template for free</li>
      <li><a href="https://www.open-resume.com/resume-parser">Resume Parser</a> parse information from a resume PDF</li>
    </ul>
  </li>
  <li>
    <p>Network and engage: Actively participate in relevant LinkedIn groups and discussions related to your field of interest. Engage with industry professionals, ask insightful questions, and build meaningful connections. Instead of solely reaching out to connections when job searching, make an effort to engage with them regularly. When you connect with someone, ask them about their work, follow their blogs, and offer your help <strong>before</strong> you ask for help. That person might be running a meetup where you can volunteer or they might be maintaining an open-source project where you can contribute. Even the intent will go a long way. Building rapport ensures that when the time comes to seek help, your requests are more likely to be received positively.</p>
  </li>
  <li>
    <p>Follow companies of interest: Identify companies you would like to work for and follow them on LinkedIn. This allows you to stay updated on their latest news, job postings, and any potential opportunities that arise. Once you see an open role, check who within your network works at that company and then make specific requests about that role. Here’s a template:</p>
  </li>
</ul>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Hi [Person2],

This is [Person1], we've spoken a few times on Hacker News and then connected on LinkedIn. I saw that your company has openings for QBasic programmers on the website. Do you know anything about this position? I'm interested in applying and would love a referral or introduction to the hiring manager/team leader if that's possible.

Appreciate your time,

[Person1]
</code></pre></div></div>

<h2 id="dont-take-this-the-wrong-way">Don’t take this the wrong way</h2>

<p>Don’t feel discouraged; seeking help is a natural part of career growth. LinkedIn is a game-changer for job seekers, but it’s crucial to use it wisely. Instead of just asking if someone knows of any open positions, let’s focus on asking for the right kind of help. By refining your requests, being specific, and actively engaging with your connections, you can increase your chances of getting meaningful assistance and rocking your job search.</p>

<p>Remember, building professional relationships takes effort, but it’s totally worth it. So, let’s put in the time and energy to connect genuinely with others. When we approach people with a clear purpose and show real interest in what they do, amazing opportunities can unfold.</p>]]></content><author><name>Dewan Ahmed</name></author><category term="networking" /><category term="linkedin" /><summary type="html"><![CDATA[I’m looking for a job in $SomeField. Do you know of any open positions?]]></summary></entry></feed>